PostgreSQL Source Code git master
Loading...
Searching...
No Matches
hash.h File Reference
#include "access/amapi.h"
#include "access/itup.h"
#include "access/sdir.h"
#include "catalog/pg_am_d.h"
#include "common/hashfn.h"
#include "lib/stringinfo.h"
#include "storage/bufmgr.h"
#include "storage/lockdefs.h"
#include "utils/hsearch.h"
#include "utils/relcache.h"
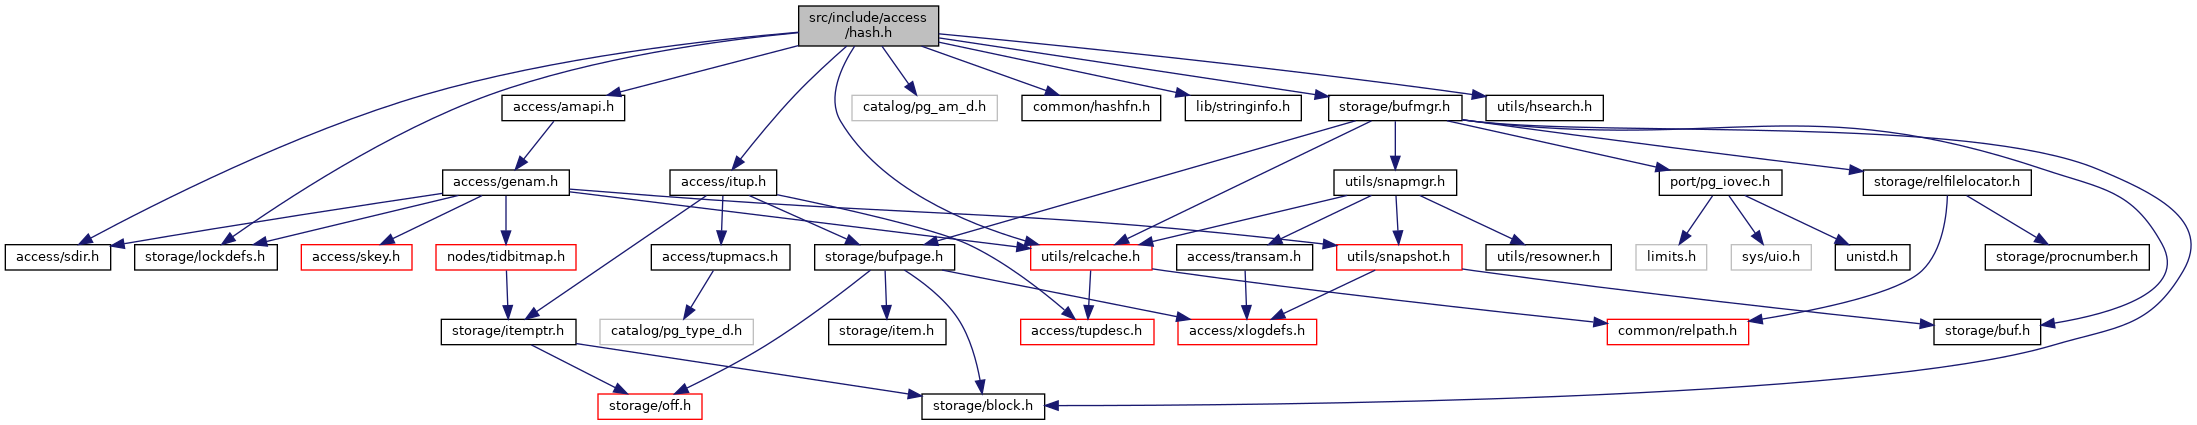
Include dependency graph for hash.h:
This graph shows which files directly or indirectly include this file:

Go to the source code of this file.

Data Structures

struct  HashPageOpaqueData
 
struct  HashScanPosItem
 
struct  HashScanPosData
 
struct  HashScanOpaqueData
 
struct  HashMetaPageData
 
struct  HashOptions
 

Macros

#define InvalidBucket   ((Bucket) 0xFFFFFFFF)
 
#define BUCKET_TO_BLKNO(metap, B)    ((BlockNumber) ((B) + ((B) ? (metap)->hashm_spares[_hash_spareindex((B)+1)-1] : 0)) + 1)
 
#define LH_UNUSED_PAGE   (0)
 
#define LH_OVERFLOW_PAGE   (1 << 0)
 
#define LH_BUCKET_PAGE   (1 << 1)
 
#define LH_BITMAP_PAGE   (1 << 2)
 
#define LH_META_PAGE   (1 << 3)
 
#define LH_BUCKET_BEING_POPULATED   (1 << 4)
 
#define LH_BUCKET_BEING_SPLIT   (1 << 5)
 
#define LH_BUCKET_NEEDS_SPLIT_CLEANUP   (1 << 6)
 
#define LH_PAGE_HAS_DEAD_TUPLES   (1 << 7)
 
#define LH_PAGE_TYPE    (LH_OVERFLOW_PAGE | LH_BUCKET_PAGE | LH_BITMAP_PAGE | LH_META_PAGE)
 
#define HashPageGetOpaque(page)   ((HashPageOpaque) PageGetSpecialPointer(page))
 
#define H_NEEDS_SPLIT_CLEANUP(opaque)   (((opaque)->hasho_flag & LH_BUCKET_NEEDS_SPLIT_CLEANUP) != 0)
 
#define H_BUCKET_BEING_SPLIT(opaque)   (((opaque)->hasho_flag & LH_BUCKET_BEING_SPLIT) != 0)
 
#define H_BUCKET_BEING_POPULATED(opaque)   (((opaque)->hasho_flag & LH_BUCKET_BEING_POPULATED) != 0)
 
#define H_HAS_DEAD_TUPLES(opaque)   (((opaque)->hasho_flag & LH_PAGE_HAS_DEAD_TUPLES) != 0)
 
#define HASHO_PAGE_ID   0xFF80
 
#define HashScanPosIsPinned(scanpos)
 
#define HashScanPosIsValid(scanpos)
 
#define HashScanPosInvalidate(scanpos)
 
#define HASH_METAPAGE   0 /* metapage is always block 0 */
 
#define HASH_MAGIC   0x6440640
 
#define HASH_VERSION   4
 
#define HASH_MAX_BITMAPS   Min(BLCKSZ / 8, 1024)
 
#define HASH_SPLITPOINT_PHASE_BITS   2
 
#define HASH_SPLITPOINT_PHASES_PER_GRP   (1 << HASH_SPLITPOINT_PHASE_BITS)
 
#define HASH_SPLITPOINT_PHASE_MASK   (HASH_SPLITPOINT_PHASES_PER_GRP - 1)
 
#define HASH_SPLITPOINT_GROUPS_WITH_ONE_PHASE   10
 
#define HASH_MAX_SPLITPOINT_GROUP   32
 
#define HASH_MAX_SPLITPOINTS
 
#define HashGetFillFactor(relation)
 
#define HashGetTargetPageUsage(relation)    (BLCKSZ * HashGetFillFactor(relation) / 100)
 
#define HashMaxItemSize(page)
 
#define INDEX_MOVED_BY_SPLIT_MASK   INDEX_AM_RESERVED_BIT
 
#define HASH_MIN_FILLFACTOR   10
 
#define HASH_DEFAULT_FILLFACTOR   75
 
#define BYTE_TO_BIT   3 /* 2^3 bits/byte */
 
#define ALL_SET   ((uint32) ~0)
 
#define BMPGSZ_BYTE(metap)   ((metap)->hashm_bmsize)
 
#define BMPGSZ_BIT(metap)   ((metap)->hashm_bmsize << BYTE_TO_BIT)
 
#define BMPG_SHIFT(metap)   ((metap)->hashm_bmshift)
 
#define BMPG_MASK(metap)   (BMPGSZ_BIT(metap) - 1)
 
#define HashPageGetBitmap(page)    ((uint32 *) PageGetContents(page))
 
#define HashGetMaxBitmapSize(page)
 
#define HashPageGetMeta(page)    ((HashMetaPage) PageGetContents(page))
 
#define BITS_PER_MAP   32 /* Number of bits in uint32 */
 
#define CLRBIT(A, N)   ((A)[(N)/BITS_PER_MAP] &= ~(1<<((N)%BITS_PER_MAP)))
 
#define SETBIT(A, N)   ((A)[(N)/BITS_PER_MAP] |= (1<<((N)%BITS_PER_MAP)))
 
#define ISSET(A, N)   ((A)[(N)/BITS_PER_MAP] & (1<<((N)%BITS_PER_MAP)))
 
#define HASH_READ   BUFFER_LOCK_SHARE
 
#define HASH_WRITE   BUFFER_LOCK_EXCLUSIVE
 
#define HASH_NOLOCK   (-1)
 
#define HASHSTANDARD_PROC   1
 
#define HASHEXTENDED_PROC   2
 
#define HASHOPTIONS_PROC   3
 
#define HASHNProcs   3
 

Typedefs

typedef uint32 Bucket
 
typedef struct HashPageOpaqueData HashPageOpaqueData
 
typedef HashPageOpaqueData * HashPageOpaque
 
typedef struct HashScanPosItem HashScanPosItem
 
typedef struct HashScanPosData HashScanPosData
 
typedef struct HashScanOpaqueData HashScanOpaqueData
 
typedef HashScanOpaqueData * HashScanOpaque
 
typedef struct HashMetaPageData HashMetaPageData
 
typedef HashMetaPageData * HashMetaPage
 
typedef struct HashOptions HashOptions
 
typedef struct HSpool HSpool
 

Functions

IndexBuildResult * hashbuild (Relation heap, Relation index, struct IndexInfo *indexInfo)
 
void hashbuildempty (Relation index)
 
bool hashinsert (Relation rel, Datum *values, bool *isnull, ItemPointer ht_ctid, Relation heapRel, IndexUniqueCheck checkUnique, bool indexUnchanged, struct IndexInfo *indexInfo)
 
bool hashgettuple (IndexScanDesc scan, ScanDirection dir)
 
int64 hashgetbitmap (IndexScanDesc scan, TIDBitmap *tbm)
 
IndexScanDesc hashbeginscan (Relation rel, int nkeys, int norderbys)
 
void hashrescan (IndexScanDesc scan, ScanKey scankey, int nscankeys, ScanKey orderbys, int norderbys)
 
void hashendscan (IndexScanDesc scan)
 
IndexBulkDeleteResult * hashbulkdelete (IndexVacuumInfo *info, IndexBulkDeleteResult *stats, IndexBulkDeleteCallback callback, void *callback_state)
 
IndexBulkDeleteResult * hashvacuumcleanup (IndexVacuumInfo *info, IndexBulkDeleteResult *stats)
 
bytea * hashoptions (Datum reloptions, bool validate)
 
bool hashvalidate (Oid opclassoid)
 
void hashadjustmembers (Oid opfamilyoid, Oid opclassoid, List *operators, List *functions)
 
CompareType hashtranslatestrategy (StrategyNumber strategy, Oid opfamily)
 
StrategyNumber hashtranslatecmptype (CompareType cmptype, Oid opfamily)
 
void _hash_doinsert (Relation rel, IndexTuple itup, Relation heapRel, bool sorted)
 
OffsetNumber _hash_pgaddtup (Relation rel, Buffer buf, Size itemsize, IndexTuple itup, bool appendtup)
 
void _hash_pgaddmultitup (Relation rel, Buffer buf, IndexTuple *itups, OffsetNumber *itup_offsets, uint16 nitups)
 
Buffer _hash_addovflpage (Relation rel, Buffer metabuf, Buffer buf, bool retain_pin)
 
BlockNumber _hash_freeovflpage (Relation rel, Buffer bucketbuf, Buffer ovflbuf, Buffer wbuf, IndexTuple *itups, OffsetNumber *itup_offsets, Size *tups_size, uint16 nitups, BufferAccessStrategy bstrategy)
 
void _hash_initbitmapbuffer (Buffer buf, uint16 bmsize, bool initpage)
 
void _hash_squeezebucket (Relation rel, Bucket bucket, BlockNumber bucket_blkno, Buffer bucket_buf, BufferAccessStrategy bstrategy)
 
uint32 _hash_ovflblkno_to_bitno (HashMetaPage metap, BlockNumber ovflblkno)
 
Buffer _hash_getbuf (Relation rel, BlockNumber blkno, int access, int flags)
 
Buffer _hash_getbuf_with_condlock_cleanup (Relation rel, BlockNumber blkno, int flags)
 
HashMetaPage _hash_getcachedmetap (Relation rel, Buffer *metabuf, bool force_refresh)
 
Buffer _hash_getbucketbuf_from_hashkey (Relation rel, uint32 hashkey, int access, HashMetaPage *cachedmetap)
 
Buffer _hash_getinitbuf (Relation rel, BlockNumber blkno)
 
void _hash_initbuf (Buffer buf, uint32 max_bucket, uint32 num_bucket, uint32 flag, bool initpage)
 
Buffer _hash_getnewbuf (Relation rel, BlockNumber blkno, ForkNumber forkNum)
 
Buffer _hash_getbuf_with_strategy (Relation rel, BlockNumber blkno, int access, int flags, BufferAccessStrategy bstrategy)
 
void _hash_relbuf (Relation rel, Buffer buf)
 
void _hash_dropbuf (Relation rel, Buffer buf)
 
void _hash_dropscanbuf (Relation rel, HashScanOpaque so)
 
uint32 _hash_init (Relation rel, double num_tuples, ForkNumber forkNum)
 
void _hash_init_metabuffer (Buffer buf, double num_tuples, RegProcedure procid, uint16 ffactor, bool initpage)
 
void _hash_pageinit (Page page, Size size)
 
void _hash_expandtable (Relation rel, Buffer metabuf)
 
void _hash_finish_split (Relation rel, Buffer metabuf, Buffer obuf, Bucket obucket, uint32 maxbucket, uint32 highmask, uint32 lowmask)
 
bool _hash_next (IndexScanDesc scan, ScanDirection dir)
 
bool _hash_first (IndexScanDesc scan, ScanDirection dir)
 
HSpool * _h_spoolinit (Relation heap, Relation index, uint32 num_buckets)
 
void _h_spooldestroy (HSpool *hspool)
 
void _h_spool (HSpool *hspool, const ItemPointerData *self, const Datum *values, const bool *isnull)
 
void _h_indexbuild (HSpool *hspool, Relation heapRel)
 
bool _hash_checkqual (IndexScanDesc scan, IndexTuple itup)
 
uint32 _hash_datum2hashkey (Relation rel, Datum key)
 
uint32 _hash_datum2hashkey_type (Relation rel, Datum key, Oid keytype)
 
Bucket _hash_hashkey2bucket (uint32 hashkey, uint32 maxbucket, uint32 highmask, uint32 lowmask)
 
uint32 _hash_spareindex (uint32 num_bucket)
 
uint32 _hash_get_totalbuckets (uint32 splitpoint_phase)
 
void _hash_checkpage (Relation rel, Buffer buf, int flags)
 
uint32 _hash_get_indextuple_hashkey (IndexTuple itup)
 
bool _hash_convert_tuple (Relation index, const Datum *user_values, const bool *user_isnull, Datum *index_values, bool *index_isnull)
 
OffsetNumber _hash_binsearch (Page page, uint32 hash_value)
 
OffsetNumber _hash_binsearch_last (Page page, uint32 hash_value)
 
BlockNumber _hash_get_oldblock_from_newbucket (Relation rel, Bucket new_bucket)
 
BlockNumber _hash_get_newblock_from_oldbucket (Relation rel, Bucket old_bucket)
 
Bucket _hash_get_newbucket_from_oldbucket (Relation rel, Bucket old_bucket, uint32 lowmask, uint32 maxbucket)
 
void _hash_kill_items (IndexScanDesc scan)
 
void hashbucketcleanup (Relation rel, Bucket cur_bucket, Buffer bucket_buf, BlockNumber bucket_blkno, BufferAccessStrategy bstrategy, uint32 maxbucket, uint32 highmask, uint32 lowmask, double *tuples_removed, double *num_index_tuples, bool split_cleanup, IndexBulkDeleteCallback callback, void *callback_state)
 

Macro Definition Documentation

◆ ALL_SET

#define ALL_SET   ((uint32) ~0)

Definition at line 302 of file hash.h.

◆ BITS_PER_MAP

#define BITS_PER_MAP   32 /* Number of bits in uint32 */

Definition at line 329 of file hash.h.

◆ BMPG_MASK

#define BMPG_MASK (   metap)    (BMPGSZ_BIT(metap) - 1)

Definition at line 314 of file hash.h.

◆ BMPG_SHIFT

#define BMPG_SHIFT (   metap)    ((metap)->hashm_bmshift)

Definition at line 313 of file hash.h.

◆ BMPGSZ_BIT

#define BMPGSZ_BIT (   metap)    ((metap)->hashm_bmsize << BYTE_TO_BIT)

Definition at line 312 of file hash.h.

◆ BMPGSZ_BYTE

#define BMPGSZ_BYTE (   metap)    ((metap)->hashm_bmsize)

Definition at line 311 of file hash.h.

◆ BUCKET_TO_BLKNO

#define BUCKET_TO_BLKNO (   metap,
  B 
)     ((BlockNumber) ((B) + ((B) ? (metap)->hashm_spares[_hash_spareindex((B)+1)-1] : 0)) + 1)

Definition at line 39 of file hash.h.

40 : 0)) + 1)

◆ BYTE_TO_BIT

#define BYTE_TO_BIT   3 /* 2^3 bits/byte */

Definition at line 301 of file hash.h.

◆ CLRBIT

#define CLRBIT (   A,
  N 
)    ((A)[(N)/BITS_PER_MAP] &= ~(1<<((N)%BITS_PER_MAP)))

Definition at line 332 of file hash.h.

◆ H_BUCKET_BEING_POPULATED

#define H_BUCKET_BEING_POPULATED (   opaque)    (((opaque)->hasho_flag & LH_BUCKET_BEING_POPULATED) != 0)

Definition at line 92 of file hash.h.

◆ H_BUCKET_BEING_SPLIT

#define H_BUCKET_BEING_SPLIT (   opaque)    (((opaque)->hasho_flag & LH_BUCKET_BEING_SPLIT) != 0)

Definition at line 91 of file hash.h.

◆ H_HAS_DEAD_TUPLES

#define H_HAS_DEAD_TUPLES (   opaque)    (((opaque)->hasho_flag & LH_PAGE_HAS_DEAD_TUPLES) != 0)

Definition at line 93 of file hash.h.

◆ H_NEEDS_SPLIT_CLEANUP

#define H_NEEDS_SPLIT_CLEANUP (   opaque)    (((opaque)->hasho_flag & LH_BUCKET_NEEDS_SPLIT_CLEANUP) != 0)

Definition at line 90 of file hash.h.

◆ HASH_DEFAULT_FILLFACTOR

#define HASH_DEFAULT_FILLFACTOR   75

Definition at line 296 of file hash.h.

◆ HASH_MAGIC

#define HASH_MAGIC   0x6440640

Definition at line 200 of file hash.h.

◆ HASH_MAX_BITMAPS

#define HASH_MAX_BITMAPS   Min(BLCKSZ / 8, 1024)

Definition at line 230 of file hash.h.

◆ HASH_MAX_SPLITPOINT_GROUP

#define HASH_MAX_SPLITPOINT_GROUP   32

Definition at line 238 of file hash.h.

◆ HASH_MAX_SPLITPOINTS

#define HASH_MAX_SPLITPOINTS
Value:
#define HASH_SPLITPOINT_GROUPS_WITH_ONE_PHASE
Definition hash.h:235
#define HASH_SPLITPOINT_PHASES_PER_GRP
Definition hash.h:233
#define HASH_MAX_SPLITPOINT_GROUP
Definition hash.h:238

Definition at line 239 of file hash.h.

◆ HASH_METAPAGE

#define HASH_METAPAGE   0 /* metapage is always block 0 */

Definition at line 198 of file hash.h.

◆ HASH_MIN_FILLFACTOR

#define HASH_MIN_FILLFACTOR   10

Definition at line 295 of file hash.h.

◆ HASH_NOLOCK

#define HASH_NOLOCK   (-1)

Definition at line 341 of file hash.h.

◆ HASH_READ

#define HASH_READ   BUFFER_LOCK_SHARE

Definition at line 339 of file hash.h.

◆ HASH_SPLITPOINT_GROUPS_WITH_ONE_PHASE

#define HASH_SPLITPOINT_GROUPS_WITH_ONE_PHASE   10

Definition at line 235 of file hash.h.

◆ HASH_SPLITPOINT_PHASE_BITS

#define HASH_SPLITPOINT_PHASE_BITS   2

Definition at line 232 of file hash.h.

◆ HASH_SPLITPOINT_PHASE_MASK

#define HASH_SPLITPOINT_PHASE_MASK   (HASH_SPLITPOINT_PHASES_PER_GRP - 1)

Definition at line 234 of file hash.h.

◆ HASH_SPLITPOINT_PHASES_PER_GRP

#define HASH_SPLITPOINT_PHASES_PER_GRP   (1 << HASH_SPLITPOINT_PHASE_BITS)

Definition at line 233 of file hash.h.

◆ HASH_VERSION

#define HASH_VERSION   4

Definition at line 201 of file hash.h.

◆ HASH_WRITE

#define HASH_WRITE   BUFFER_LOCK_EXCLUSIVE

Definition at line 340 of file hash.h.

◆ HASHEXTENDED_PROC

#define HASHEXTENDED_PROC   2

Definition at line 356 of file hash.h.

◆ HashGetFillFactor

#define HashGetFillFactor (   relation)
Value:
(AssertMacro(relation->rd_rel->relkind == RELKIND_INDEX && \
relation->rd_rel->relam == HASH_AM_OID), \
(relation)->rd_options ? \
((HashOptions *) (relation)->rd_options)->fillfactor : \
#define AssertMacro(condition)
Definition c.h:1003
#define HASH_DEFAULT_FILLFACTOR
Definition hash.h:296
static int fb(int x)

Definition at line 275 of file hash.h.

◆ HashGetMaxBitmapSize

#define HashGetMaxBitmapSize (   page)
Value:
(PageGetPageSize((Page) page) - \
static Size PageGetPageSize(const PageData *page)
Definition bufpage.h:301
#define SizeOfPageHeaderData
Definition bufpage.h:241
PageData * Page
Definition bufpage.h:81
#define MAXALIGN(LEN)
Definition c.h:955

Definition at line 319 of file hash.h.

◆ HashGetTargetPageUsage

#define HashGetTargetPageUsage (   relation)     (BLCKSZ * HashGetFillFactor(relation) / 100)

Definition at line 281 of file hash.h.

◆ HashMaxItemSize

#define HashMaxItemSize (   page)
Value:
sizeof(ItemIdData) - \
#define MAXALIGN_DOWN(LEN)
Definition c.h:967

Definition at line 287 of file hash.h.

◆ HASHNProcs

#define HASHNProcs   3

Definition at line 358 of file hash.h.

◆ HASHO_PAGE_ID

#define HASHO_PAGE_ID   0xFF80

Definition at line 101 of file hash.h.

◆ HASHOPTIONS_PROC

#define HASHOPTIONS_PROC   3

Definition at line 357 of file hash.h.

◆ HashPageGetBitmap

#define HashPageGetBitmap (   page)     ((uint32 *) PageGetContents(page))

Definition at line 316 of file hash.h.

◆ HashPageGetMeta

#define HashPageGetMeta (   page)     ((HashMetaPage) PageGetContents(page))

Definition at line 323 of file hash.h.

◆ HashPageGetOpaque

#define HashPageGetOpaque (   page)    ((HashPageOpaque) PageGetSpecialPointer(page))

Definition at line 88 of file hash.h.

◆ HashScanPosInvalidate

#define HashScanPosInvalidate (   scanpos)
Value:
do { \
(scanpos).currPage = InvalidBlockNumber; \
(scanpos).nextPage = InvalidBlockNumber; \
(scanpos).prevPage = InvalidBlockNumber; \
(scanpos).firstItem = 0; \
(scanpos).lastItem = 0; \
(scanpos).itemIndex = 0; \
} while (0)
#define InvalidBlockNumber
Definition block.h:33
#define InvalidBuffer
Definition buf.h:25
static char buf[DEFAULT_XLOG_SEG_SIZE]

Definition at line 144 of file hash.h.

145 { \
147 (scanpos).currPage = InvalidBlockNumber; \
148 (scanpos).nextPage = InvalidBlockNumber; \
149 (scanpos).prevPage = InvalidBlockNumber; \
150 (scanpos).firstItem = 0; \
151 (scanpos).lastItem = 0; \
152 (scanpos).itemIndex = 0; \
153 } while (0)

◆ HashScanPosIsPinned

#define HashScanPosIsPinned (   scanpos)
Value:
( \
)
static bool BlockNumberIsValid(BlockNumber blockNumber)
Definition block.h:71
static bool BufferIsValid(Buffer bufnum)
Definition bufmgr.h:419

Definition at line 130 of file hash.h.

◆ HashScanPosIsValid

#define HashScanPosIsValid (   scanpos)
Value:

Definition at line 137 of file hash.h.

◆ HASHSTANDARD_PROC

#define HASHSTANDARD_PROC   1

Definition at line 355 of file hash.h.

◆ INDEX_MOVED_BY_SPLIT_MASK

#define INDEX_MOVED_BY_SPLIT_MASK   INDEX_AM_RESERVED_BIT

Definition at line 293 of file hash.h.

◆ InvalidBucket

#define InvalidBucket   ((Bucket) 0xFFFFFFFF)

Definition at line 37 of file hash.h.

◆ ISSET

#define ISSET (   A,
  N 
)    ((A)[(N)/BITS_PER_MAP] & (1<<((N)%BITS_PER_MAP)))

Definition at line 334 of file hash.h.

◆ LH_BITMAP_PAGE

#define LH_BITMAP_PAGE   (1 << 2)

Definition at line 56 of file hash.h.

◆ LH_BUCKET_BEING_POPULATED

#define LH_BUCKET_BEING_POPULATED   (1 << 4)

Definition at line 58 of file hash.h.

◆ LH_BUCKET_BEING_SPLIT

#define LH_BUCKET_BEING_SPLIT   (1 << 5)

Definition at line 59 of file hash.h.

◆ LH_BUCKET_NEEDS_SPLIT_CLEANUP

#define LH_BUCKET_NEEDS_SPLIT_CLEANUP   (1 << 6)

Definition at line 60 of file hash.h.

◆ LH_BUCKET_PAGE

#define LH_BUCKET_PAGE   (1 << 1)

Definition at line 55 of file hash.h.

◆ LH_META_PAGE

#define LH_META_PAGE   (1 << 3)

Definition at line 57 of file hash.h.

◆ LH_OVERFLOW_PAGE

#define LH_OVERFLOW_PAGE   (1 << 0)

Definition at line 54 of file hash.h.

◆ LH_PAGE_HAS_DEAD_TUPLES

#define LH_PAGE_HAS_DEAD_TUPLES   (1 << 7)

Definition at line 61 of file hash.h.

◆ LH_PAGE_TYPE

Definition at line 63 of file hash.h.

◆ LH_UNUSED_PAGE

#define LH_UNUSED_PAGE   (0)

Definition at line 53 of file hash.h.

◆ SETBIT

#define SETBIT (   A,
  N 
)    ((A)[(N)/BITS_PER_MAP] |= (1<<((N)%BITS_PER_MAP)))

Definition at line 333 of file hash.h.

Typedef Documentation

◆ Bucket

Definition at line 35 of file hash.h.

◆ HashMetaPage

Definition at line 267 of file hash.h.

◆ HashMetaPageData

◆ HashOptions

◆ HashPageOpaque

Definition at line 86 of file hash.h.

◆ HashPageOpaqueData

◆ HashScanOpaque

Definition at line 192 of file hash.h.

◆ HashScanOpaqueData

◆ HashScanPosData

◆ HashScanPosItem

◆ HSpool

Definition at line 452 of file hash.h.

Function Documentation

◆ _h_indexbuild()

void _h_indexbuild ( HSpool *  hspool,
Relation  heapRel 
)
extern

Definition at line 120 of file hashsort.c.

121{
122 IndexTuple itup;
123 int64 tups_done = 0;
124#ifdef USE_ASSERT_CHECKING
125 uint32 hashkey = 0;
126#endif
127
128 tuplesort_performsort(hspool->sortstate);
129
130 while ((itup = tuplesort_getindextuple(hspool->sortstate, true)) != NULL)
131 {
132 /*
133 * Technically, it isn't critical that hash keys be found in sorted
134 * order, since this sorting is only used to increase locality of
135 * access as a performance optimization. It still seems like a good
136 * idea to test tuplesort.c's handling of hash index tuple sorts
137 * through an assertion, though.
138 */
139#ifdef USE_ASSERT_CHECKING
141
143 hspool->max_buckets, hspool->high_mask,
144 hspool->low_mask);
146#endif
147
148 /* the tuples are sorted by hashkey, so pass 'sorted' as true */
149 _hash_doinsert(hspool->index, itup, heapRel, true);
150
151 /* allow insertion phase to be interrupted, and track progress */
153
155 ++tups_done);
156 }
157}
void pgstat_progress_update_param(int index, int64 val)
#define Assert(condition)
Definition c.h:1002
int64_t int64
Definition c.h:680
uint32_t uint32
Definition c.h:683
void _hash_doinsert(Relation rel, IndexTuple itup, Relation heapRel, bool sorted)
Definition hashinsert.c:38
uint32 _hash_get_indextuple_hashkey(IndexTuple itup)
Definition hashutil.c:291
Bucket _hash_hashkey2bucket(uint32 hashkey, uint32 maxbucket, uint32 highmask, uint32 lowmask)
Definition hashutil.c:125
#define CHECK_FOR_INTERRUPTS()
Definition miscadmin.h:125
#define PROGRESS_CREATEIDX_TUPLES_DONE
Definition progress.h:116
void tuplesort_performsort(Tuplesortstate *state)
Definition tuplesort.c:1260
IndexTuple tuplesort_getindextuple(Tuplesortstate *state, bool forward)

References _hash_doinsert(), _hash_get_indextuple_hashkey(), _hash_hashkey2bucket(), Assert, CHECK_FOR_INTERRUPTS, fb(), pgstat_progress_update_param(), PROGRESS_CREATEIDX_TUPLES_DONE, tuplesort_getindextuple(), and tuplesort_performsort().

Referenced by hashbuild().

◆ _h_spool()

void _h_spool ( HSpool *  hspool,
const ItemPointerData *  self,
const Datum *  values,
const bool *  isnull 
)
extern

Definition at line 109 of file hashsort.c.

110{
112 self, values, isnull);
113}
static Datum values[MAXATTR]
Definition bootstrap.c:190
void tuplesort_putindextuplevalues(Tuplesortstate *state, Relation rel, const ItemPointerData *self, const Datum *values, const bool *isnull)

References fb(), tuplesort_putindextuplevalues(), and values.

Referenced by hashbuildCallback().

◆ _h_spooldestroy()

void _h_spooldestroy ( HSpool *  hspool)
extern

Definition at line 99 of file hashsort.c.

100{
101 tuplesort_end(hspool->sortstate);
102 pfree(hspool);
103}
void pfree(void *pointer)
Definition mcxt.c:1619
void tuplesort_end(Tuplesortstate *state)
Definition tuplesort.c:848

References fb(), pfree(), and tuplesort_end().

Referenced by hashbuild().

◆ _h_spoolinit()

HSpool * _h_spoolinit ( Relation  heap,
Relation  index,
uint32  num_buckets 
)
extern

Definition at line 60 of file hashsort.c.

61{
63
64 hspool->index = index;
65
66 /*
67 * Determine the bitmask for hash code values. Since there are currently
68 * num_buckets buckets in the index, the appropriate mask can be computed
69 * as follows.
70 *
71 * NOTE : This hash mask calculation should be in sync with similar
72 * calculation in _hash_init_metabuffer.
73 */
74 hspool->high_mask = pg_nextpower2_32(num_buckets + 1) - 1;
75 hspool->low_mask = (hspool->high_mask >> 1);
76 hspool->max_buckets = num_buckets - 1;
77
78 /*
79 * We size the sort area as maintenance_work_mem rather than work_mem to
80 * speed index creation. This should be OK since a single backend can't
81 * run multiple index creations in parallel.
82 */
83 hspool->sortstate = tuplesort_begin_index_hash(heap,
84 index,
85 hspool->high_mask,
86 hspool->low_mask,
87 hspool->max_buckets,
89 NULL,
91
92 return hspool;
93}
#define palloc0_object(type)
Definition fe_memutils.h:90
int maintenance_work_mem
Definition globals.c:135
static uint32 pg_nextpower2_32(uint32 num)
Definition type.h:97
#define TUPLESORT_NONE
Definition tuplesort.h:67
Tuplesortstate * tuplesort_begin_index_hash(Relation heapRel, Relation indexRel, uint32 high_mask, uint32 low_mask, uint32 max_buckets, int workMem, SortCoordinate coordinate, int sortopt)

References fb(), maintenance_work_mem, palloc0_object, pg_nextpower2_32(), tuplesort_begin_index_hash(), and TUPLESORT_NONE.

Referenced by hashbuild().

◆ _hash_addovflpage()

Buffer _hash_addovflpage ( Relation  rel,
Buffer  metabuf,
Buffer  buf,
bool  retain_pin 
)
extern

Definition at line 112 of file hashovfl.c.

113{
115 Page page;
119 HashMetaPage metap;
122 BlockNumber blkno;
125 uint32 *freep = NULL;
127 uint32 bit;
129 uint32 first_page;
132 uint32 i,
133 j;
134 bool page_found = false;
136
137 /*
138 * Write-lock the tail page. Here, we need to maintain locking order such
139 * that, first acquire the lock on tail page of bucket, then on meta page
140 * to find and lock the bitmap page and if it is found, then lock on meta
141 * page is released, then finally acquire the lock on new overflow buffer.
142 * We need this locking order to avoid deadlock with backends that are
143 * doing inserts.
144 *
145 * Note: We could have avoided locking many buffers here if we made two
146 * WAL records for acquiring an overflow page (one to allocate an overflow
147 * page and another to add it to overflow bucket chain). However, doing
148 * so can leak an overflow page, if the system crashes after allocation.
149 * Needless to say, it is better to have a single record from a
150 * performance point of view as well.
151 */
153
154 /* probably redundant... */
156
157 /* loop to find current tail page, in case someone else inserted too */
158 for (;;)
159 {
160 BlockNumber nextblkno;
161
162 page = BufferGetPage(buf);
164 nextblkno = pageopaque->hasho_nextblkno;
165
166 if (!BlockNumberIsValid(nextblkno))
167 break;
168
169 /* we assume we do not need to write the unmodified page */
170 if (retain_pin)
171 {
172 /* pin will be retained only for the primary bucket page */
173 Assert((pageopaque->hasho_flag & LH_PAGE_TYPE) == LH_BUCKET_PAGE);
175 }
176 else
177 _hash_relbuf(rel, buf);
178
179 retain_pin = false;
180
181 buf = _hash_getbuf(rel, nextblkno, HASH_WRITE, LH_OVERFLOW_PAGE);
182 }
183
184 /* Get exclusive lock on the meta page */
186
189
190 /* start search at hashm_firstfree */
192 first_page = orig_firstfree >> BMPG_SHIFT(metap);
193 bit = orig_firstfree & BMPG_MASK(metap);
194 i = first_page;
195 j = bit / BITS_PER_MAP;
196 bit &= ~(BITS_PER_MAP - 1);
197
198 /* outer loop iterates once per bitmap page */
199 for (;;)
200 {
204
205 /* want to end search with the last existing overflow page */
206 splitnum = metap->hashm_ovflpoint;
207 max_ovflpg = metap->hashm_spares[splitnum] - 1;
208 last_page = max_ovflpg >> BMPG_SHIFT(metap);
209 last_bit = max_ovflpg & BMPG_MASK(metap);
210
211 if (i > last_page)
212 break;
213
214 Assert(i < metap->hashm_nmaps);
215 mapblkno = metap->hashm_mapp[i];
216
217 if (i == last_page)
219 else
220 last_inpage = BMPGSZ_BIT(metap) - 1;
221
222 /* Release exclusive lock on metapage while reading bitmap page */
224
228
229 for (; bit <= last_inpage; j++, bit += BITS_PER_MAP)
230 {
231 if (freep[j] != ALL_SET)
232 {
233 page_found = true;
234
235 /* Reacquire exclusive lock on the meta page */
237
238 /* convert bit to bit number within page */
241
242 /* convert bit to absolute bit number */
243 bit += (i << BMPG_SHIFT(metap));
244 /* Calculate address of the recycled overflow page */
245 blkno = bitno_to_blkno(metap, bit);
246
247 /* Fetch and init the recycled page */
248 ovflbuf = _hash_getinitbuf(rel, blkno);
249
250 goto found;
251 }
252 }
253
254 /* No free space here, try to advance to next map page */
255 _hash_relbuf(rel, mapbuf);
257 i++;
258 j = 0; /* scan from start of next map page */
259 bit = 0;
260
261 /* Reacquire exclusive lock on the meta page */
263 }
264
265 /*
266 * No free pages --- have to extend the relation to add an overflow page.
267 * First, check to see if we have to add a new bitmap page too.
268 */
269 if (last_bit == (uint32) (BMPGSZ_BIT(metap) - 1))
270 {
271 /*
272 * We create the new bitmap page with all pages marked "in use".
273 * Actually two pages in the new bitmap's range will exist
274 * immediately: the bitmap page itself, and the following page which
275 * is the one we return to the caller. Both of these are correctly
276 * marked "in use". Subsequent pages do not exist yet, but it is
277 * convenient to pre-mark them as "in use" too.
278 */
279 bit = metap->hashm_spares[splitnum];
280
281 /* metapage already has a write lock */
282 if (metap->hashm_nmaps >= HASH_MAX_BITMAPS)
285 errmsg("out of overflow pages in hash index \"%s\"",
287
289 }
290 else
291 {
292 /*
293 * Nothing to do here; since the page will be past the last used page,
294 * we know its bitmap bit was preinitialized to "in use".
295 */
296 }
297
298 /* Calculate address of the new overflow page */
300 metap->hashm_spares[splitnum] + 1 : metap->hashm_spares[splitnum];
301 blkno = bitno_to_blkno(metap, bit);
302
303 /*
304 * Fetch the page with _hash_getnewbuf to ensure smgr's idea of the
305 * relation length stays in sync with ours. XXX It's annoying to do this
306 * with metapage write lock held; would be better to use a lock that
307 * doesn't block incoming searches.
308 *
309 * It is okay to hold two buffer locks here (one on tail page of bucket
310 * and other on new overflow page) since there cannot be anyone else
311 * contending for access to ovflbuf.
312 */
313 ovflbuf = _hash_getnewbuf(rel, blkno, MAIN_FORKNUM);
314
315found:
316
317 /*
318 * Do the update. No ereport(ERROR) until changes are logged. We want to
319 * log the changes for bitmap page and overflow page together to avoid
320 * loss of pages in case the new page is added.
321 */
323
324 if (page_found)
325 {
327
328 /* mark page "in use" in the bitmap */
331 }
332 else
333 {
334 /* update the count to indicate new overflow page is added */
335 metap->hashm_spares[splitnum]++;
336
338 {
341
342 /* add the new bitmap page to the metapage's list of bitmaps */
344 metap->hashm_nmaps++;
345 metap->hashm_spares[splitnum]++;
346 }
347
349
350 /*
351 * for new overflow page, we don't need to explicitly set the bit in
352 * bitmap page, as by default that will be set to "in use".
353 */
354 }
355
356 /*
357 * Adjust hashm_firstfree to avoid redundant searches. But don't risk
358 * changing it if someone moved it while we were searching bitmap pages.
359 */
360 if (metap->hashm_firstfree == orig_firstfree)
361 {
362 metap->hashm_firstfree = bit + 1;
364 }
365
366 /* initialize new overflow page */
369 ovflopaque->hasho_prevblkno = BufferGetBlockNumber(buf);
370 ovflopaque->hasho_nextblkno = InvalidBlockNumber;
371 ovflopaque->hasho_bucket = pageopaque->hasho_bucket;
372 ovflopaque->hasho_flag = LH_OVERFLOW_PAGE;
373 ovflopaque->hasho_page_id = HASHO_PAGE_ID;
374
376
377 /* logically chain overflow page to previous page */
378 pageopaque->hasho_nextblkno = BufferGetBlockNumber(ovflbuf);
379
381
382 /* XLOG stuff */
383 if (RelationNeedsWAL(rel))
384 {
386
388 xlrec.bmsize = metap->hashm_bmsize;
389
392
394 XLogRegisterBufData(0, &pageopaque->hasho_bucket, sizeof(Bucket));
395
397
399 {
402 }
403
406
408 XLogRegisterBufData(4, &metap->hashm_firstfree, sizeof(uint32));
409
411 }
412 else
413 recptr = XLogGetFakeLSN(rel);
414
417
420
423
425
427
428 if (retain_pin)
430 else
431 _hash_relbuf(rel, buf);
432
434 _hash_relbuf(rel, mapbuf);
435
437
440
441 return ovflbuf;
442}
uint32 BlockNumber
Definition block.h:31
#define SETBIT(x, i)
Definition blutils.c:29
int Buffer
Definition buf.h:23
BlockNumber BufferGetBlockNumber(Buffer buffer)
Definition bufmgr.c:4469
void MarkBufferDirty(Buffer buffer)
Definition bufmgr.c:3170
static Page BufferGetPage(Buffer buffer)
Definition bufmgr.h:468
@ BUFFER_LOCK_EXCLUSIVE
Definition bufmgr.h:222
@ BUFFER_LOCK_UNLOCK
Definition bufmgr.h:207
static void LockBuffer(Buffer buffer, BufferLockMode mode)
Definition bufmgr.h:334
static void PageSetLSN(Page page, XLogRecPtr lsn)
Definition bufpage.h:416
int errcode(int sqlerrcode)
Definition elog.c:875
#define ERROR
Definition elog.h:40
#define ereport(elevel,...)
Definition elog.h:152
#define HashPageGetOpaque(page)
Definition hash.h:88
#define LH_BUCKET_PAGE
Definition hash.h:55
#define HASH_MAX_BITMAPS
Definition hash.h:230
#define BMPG_MASK(metap)
Definition hash.h:314
#define HASH_WRITE
Definition hash.h:340
#define BITS_PER_MAP
Definition hash.h:329
#define HashPageGetBitmap(page)
Definition hash.h:316
#define LH_META_PAGE
Definition hash.h:57
#define HASHO_PAGE_ID
Definition hash.h:101
#define HashPageGetMeta(page)
Definition hash.h:323
#define BMPGSZ_BIT(metap)
Definition hash.h:312
#define LH_PAGE_TYPE
Definition hash.h:63
uint32 Bucket
Definition hash.h:35
#define ALL_SET
Definition hash.h:302
#define LH_BITMAP_PAGE
Definition hash.h:56
#define BMPG_SHIFT(metap)
Definition hash.h:313
#define LH_OVERFLOW_PAGE
Definition hash.h:54
#define SizeOfHashAddOvflPage
Definition hash_xlog.h:80
#define XLOG_HASH_ADD_OVFL_PAGE
Definition hash_xlog.h:30
static uint32 _hash_firstfreebit(uint32 map)
Definition hashovfl.c:450
void _hash_initbitmapbuffer(Buffer buf, uint16 bmsize, bool initpage)
Definition hashovfl.c:778
static BlockNumber bitno_to_blkno(HashMetaPage metap, uint32 ovflbitnum)
Definition hashovfl.c:35
Buffer _hash_getinitbuf(Relation rel, BlockNumber blkno)
Definition hashpage.c:135
void _hash_relbuf(Relation rel, Buffer buf)
Definition hashpage.c:266
Buffer _hash_getbuf(Relation rel, BlockNumber blkno, int access, int flags)
Definition hashpage.c:70
Buffer _hash_getnewbuf(Relation rel, BlockNumber blkno, ForkNumber forkNum)
Definition hashpage.c:198
void _hash_checkpage(Relation rel, Buffer buf, int flags)
Definition hashutil.c:210
int j
Definition isn.c:78
int i
Definition isn.c:77
#define START_CRIT_SECTION()
Definition miscadmin.h:152
#define END_CRIT_SECTION()
Definition miscadmin.h:154
static char * errmsg
#define RelationGetRelationName(relation)
Definition rel.h:550
#define RelationNeedsWAL(relation)
Definition rel.h:639
@ MAIN_FORKNUM
Definition relpath.h:58
BlockNumber hashm_mapp[HASH_MAX_BITMAPS]
Definition hash.h:264
uint32 hashm_spares[HASH_MAX_SPLITPOINTS]
Definition hash.h:262
uint32 hashm_firstfree
Definition hash.h:259
uint16 hashm_bmsize
Definition hash.h:251
uint32 hashm_ovflpoint
Definition hash.h:257
uint32 hashm_nmaps
Definition hash.h:260
Datum bit(PG_FUNCTION_ARGS)
Definition varbit.c:391
uint64 XLogRecPtr
Definition xlogdefs.h:21
XLogRecPtr XLogInsert(RmgrId rmid, uint8 info)
Definition xloginsert.c:482
void XLogRegisterBufData(uint8 block_id, const void *data, uint32 len)
Definition xloginsert.c:413
void XLogRegisterData(const void *data, uint32 len)
Definition xloginsert.c:372
void XLogRegisterBuffer(uint8 block_id, Buffer buffer, uint8 flags)
Definition xloginsert.c:246
void XLogBeginInsert(void)
Definition xloginsert.c:153
XLogRecPtr XLogGetFakeLSN(Relation rel)
Definition xloginsert.c:562
#define REGBUF_STANDARD
Definition xloginsert.h:35
#define REGBUF_WILL_INIT
Definition xloginsert.h:34

References _hash_checkpage(), _hash_firstfreebit(), _hash_getbuf(), _hash_getinitbuf(), _hash_getnewbuf(), _hash_initbitmapbuffer(), _hash_relbuf(), ALL_SET, Assert, bit(), bitno_to_blkno(), BITS_PER_MAP, BlockNumberIsValid(), xl_hash_add_ovfl_page::bmpage_found, BMPG_MASK, BMPG_SHIFT, BMPGSZ_BIT, buf, BUFFER_LOCK_EXCLUSIVE, BUFFER_LOCK_UNLOCK, BufferGetBlockNumber(), BufferGetPage(), BufferIsValid(), END_CRIT_SECTION, ereport, errcode(), errmsg, ERROR, fb(), HASH_MAX_BITMAPS, HASH_WRITE, HashMetaPageData::hashm_bmsize, HashMetaPageData::hashm_firstfree, HashMetaPageData::hashm_mapp, HashMetaPageData::hashm_nmaps, HashMetaPageData::hashm_ovflpoint, HashMetaPageData::hashm_spares, HASHO_PAGE_ID, HashPageGetBitmap, HashPageGetMeta, HashPageGetOpaque, i, InvalidBlockNumber, InvalidBuffer, j, LH_BITMAP_PAGE, LH_BUCKET_PAGE, LH_META_PAGE, LH_OVERFLOW_PAGE, LH_PAGE_TYPE, LockBuffer(), MAIN_FORKNUM, MarkBufferDirty(), PageSetLSN(), REGBUF_STANDARD, REGBUF_WILL_INIT, RelationGetRelationName, RelationNeedsWAL, SETBIT, SizeOfHashAddOvflPage, START_CRIT_SECTION, XLOG_HASH_ADD_OVFL_PAGE, XLogBeginInsert(), XLogGetFakeLSN(), XLogInsert(), XLogRegisterBufData(), XLogRegisterBuffer(), and XLogRegisterData().

Referenced by _hash_doinsert(), and _hash_splitbucket().

◆ _hash_binsearch()

OffsetNumber _hash_binsearch ( Page  page,
uint32  hash_value 
)
extern

Definition at line 350 of file hashutil.c.

351{
354
355 /* Loop invariant: lower <= desired place <= upper */
356 upper = PageGetMaxOffsetNumber(page) + 1;
358
359 while (upper > lower)
360 {
361 OffsetNumber off;
362 IndexTuple itup;
364
365 off = (upper + lower) / 2;
367
368 itup = (IndexTuple) PageGetItem(page, PageGetItemId(page, off));
370 if (hashkey < hash_value)
371 lower = off + 1;
372 else
373 upper = off;
374 }
375
376 return lower;
377}
static ItemId PageGetItemId(Page page, OffsetNumber offsetNumber)
Definition bufpage.h:268
static void * PageGetItem(PageData *page, const ItemIdData *itemId)
Definition bufpage.h:378
static OffsetNumber PageGetMaxOffsetNumber(const PageData *page)
Definition bufpage.h:396
IndexTupleData * IndexTuple
Definition itup.h:53
#define OffsetNumberIsValid(offsetNumber)
Definition off.h:39
uint16 OffsetNumber
Definition off.h:24
#define FirstOffsetNumber
Definition off.h:27
Datum lower(PG_FUNCTION_ARGS)
Datum upper(PG_FUNCTION_ARGS)

References _hash_get_indextuple_hashkey(), Assert, fb(), FirstOffsetNumber, lower(), OffsetNumberIsValid, PageGetItem(), PageGetItemId(), PageGetMaxOffsetNumber(), and upper().

Referenced by _hash_pgaddmultitup(), _hash_pgaddtup(), and _hash_readpage().

◆ _hash_binsearch_last()

OffsetNumber _hash_binsearch_last ( Page  page,
uint32  hash_value 
)
extern

Definition at line 388 of file hashutil.c.

389{
392
393 /* Loop invariant: lower <= desired place <= upper */
396
397 while (upper > lower)
398 {
399 IndexTuple itup;
400 OffsetNumber off;
402
403 off = (upper + lower + 1) / 2;
405
406 itup = (IndexTuple) PageGetItem(page, PageGetItemId(page, off));
408 if (hashkey > hash_value)
409 upper = off - 1;
410 else
411 lower = off;
412 }
413
414 return lower;
415}

References _hash_get_indextuple_hashkey(), Assert, fb(), FirstOffsetNumber, lower(), OffsetNumberIsValid, PageGetItem(), PageGetItemId(), PageGetMaxOffsetNumber(), and upper().

Referenced by _hash_readpage().

◆ _hash_checkpage()

void _hash_checkpage ( Relation  rel,
Buffer  buf,
int  flags 
)
extern

Definition at line 210 of file hashutil.c.

211{
212 Page page = BufferGetPage(buf);
213
214 /*
215 * ReadBuffer verifies that every newly-read page passes
216 * PageHeaderIsValid, which means it either contains a reasonably sane
217 * page header or is all-zero. We have to defend against the all-zero
218 * case, however.
219 */
220 if (PageIsNew(page))
223 errmsg("index \"%s\" contains unexpected zero page at block %u",
226 errhint("Please REINDEX it.")));
227
228 /*
229 * Additionally check that the special area looks sane.
230 */
231 if (PageGetSpecialSize(page) != MAXALIGN(sizeof(HashPageOpaqueData)))
234 errmsg("index \"%s\" contains corrupted page at block %u",
237 errhint("Please REINDEX it.")));
238
239 if (flags)
240 {
241 HashPageOpaque opaque = HashPageGetOpaque(page);
242
243 if ((opaque->hasho_flag & flags) == 0)
246 errmsg("index \"%s\" contains corrupted page at block %u",
249 errhint("Please REINDEX it.")));
250 }
251
252 /*
253 * When checking the metapage, also verify magic number and version.
254 */
255 if (flags == LH_META_PAGE)
256 {
257 HashMetaPage metap = HashPageGetMeta(page);
258
259 if (metap->hashm_magic != HASH_MAGIC)
262 errmsg("index \"%s\" is not a hash index",
264
265 if (metap->hashm_version != HASH_VERSION)
268 errmsg("index \"%s\" has wrong hash version",
270 errhint("Please REINDEX it.")));
271 }
272}
static uint16 PageGetSpecialSize(const PageData *page)
Definition bufpage.h:341
static bool PageIsNew(const PageData *page)
Definition bufpage.h:258
int errhint(const char *fmt,...) pg_attribute_printf(1
#define HASH_VERSION
Definition hash.h:201
#define HASH_MAGIC
Definition hash.h:200
uint32 hashm_version
Definition hash.h:247
uint32 hashm_magic
Definition hash.h:246
uint16 hasho_flag
Definition hash.h:82

References buf, BufferGetBlockNumber(), BufferGetPage(), ereport, errcode(), errhint(), errmsg, ERROR, fb(), HASH_MAGIC, HASH_VERSION, HashMetaPageData::hashm_magic, HashMetaPageData::hashm_version, HashPageOpaqueData::hasho_flag, HashPageGetMeta, HashPageGetOpaque, LH_META_PAGE, MAXALIGN, PageGetSpecialSize(), PageIsNew(), and RelationGetRelationName.

Referenced by _hash_addovflpage(), _hash_expandtable(), _hash_freeovflpage(), _hash_getbuf(), _hash_getbuf_with_condlock_cleanup(), _hash_getbuf_with_strategy(), _hash_pgaddmultitup(), _hash_pgaddtup(), _hash_readpage(), and hashbulkdelete().

◆ _hash_checkqual()

bool _hash_checkqual ( IndexScanDesc  scan,
IndexTuple  itup 
)
extern

Definition at line 31 of file hashutil.c.

32{
33 /*
34 * Currently, we can't check any of the scan conditions since we do not
35 * have the original index entry value to supply to the sk_func. Always
36 * return true; we expect that hashgettuple already set the recheck flag
37 * to make the main indexscan code do it.
38 */
39#ifdef NOT_USED
41 ScanKey key = scan->keyData;
42 int scanKeySize = scan->numberOfKeys;
43
44 while (scanKeySize > 0)
45 {
46 Datum datum;
47 bool isNull;
48 Datum test;
49
50 datum = index_getattr(itup,
51 key->sk_attno,
52 tupdesc,
53 &isNull);
54
55 /* assume sk_func is strict */
56 if (isNull)
57 return false;
58 if (key->sk_flags & SK_ISNULL)
59 return false;
60
61 test = FunctionCall2Coll(&key->sk_func, key->sk_collation,
62 datum, key->sk_argument);
63
64 if (!DatumGetBool(test))
65 return false;
66
67 key++;
69 }
70#endif
71
72 return true;
73}
Datum FunctionCall2Coll(FmgrInfo *flinfo, Oid collation, Datum arg1, Datum arg2)
Definition fmgr.c:1151
static Datum index_getattr(IndexTuple tup, int attnum, TupleDesc tupleDesc, bool *isnull)
Definition itup.h:131
static bool DatumGetBool(Datum X)
Definition postgres.h:100
uint64_t Datum
Definition postgres.h:70
static void test(void)
#define RelationGetDescr(relation)
Definition rel.h:542
#define SK_ISNULL
Definition skey.h:115
struct ScanKeyData * keyData
Definition relscan.h:154
Relation indexRelation
Definition relscan.h:150

References DatumGetBool(), fb(), FunctionCall2Coll(), index_getattr(), IndexScanDescData::indexRelation, IndexScanDescData::keyData, IndexScanDescData::numberOfKeys, RelationGetDescr, SK_ISNULL, and test().

Referenced by _hash_load_qualified_items().

◆ _hash_convert_tuple()

bool _hash_convert_tuple ( Relation  index,
const Datum *  user_values,
const bool *  user_isnull,
Datum *  index_values,
bool *  index_isnull 
)
extern

Definition at line 318 of file hashutil.c.

321{
323
324 /*
325 * We do not insert null values into hash indexes. This is okay because
326 * the only supported search operator is '=', and we assume it is strict.
327 */
328 if (user_isnull[0])
329 return false;
330
333 index_isnull[0] = false;
334 return true;
335}
uint32 _hash_datum2hashkey(Relation rel, Datum key)
Definition hashutil.c:82
static Datum UInt32GetDatum(uint32 X)
Definition postgres.h:232

References _hash_datum2hashkey(), fb(), and UInt32GetDatum().

Referenced by hashbuildCallback(), and hashinsert().

◆ _hash_datum2hashkey()

uint32 _hash_datum2hashkey ( Relation  rel,
Datum  key 
)
extern

Definition at line 82 of file hashutil.c.

83{
85 Oid collation;
86
87 /* XXX assumes index has only one attribute */
89 collation = rel->rd_indcollation[0];
90
91 return DatumGetUInt32(FunctionCall1Coll(procinfo, collation, key));
92}
Datum FunctionCall1Coll(FmgrInfo *flinfo, Oid collation, Datum arg1)
Definition fmgr.c:1131
#define HASHSTANDARD_PROC
Definition hash.h:355
FmgrInfo * index_getprocinfo(Relation irel, AttrNumber attnum, uint16 procnum)
Definition indexam.c:885
static uint32 DatumGetUInt32(Datum X)
Definition postgres.h:222
unsigned int Oid
Oid * rd_indcollation
Definition rel.h:217

References DatumGetUInt32(), fb(), FunctionCall1Coll(), HASHSTANDARD_PROC, index_getprocinfo(), and RelationData::rd_indcollation.

Referenced by _hash_convert_tuple(), and _hash_first().

◆ _hash_datum2hashkey_type()

uint32 _hash_datum2hashkey_type ( Relation  rel,
Datum  key,
Oid  keytype 
)
extern

Definition at line 102 of file hashutil.c.

103{
104 RegProcedure hash_proc;
105 Oid collation;
106
107 /* XXX assumes index has only one attribute */
108 hash_proc = get_opfamily_proc(rel->rd_opfamily[0],
109 keytype,
110 keytype,
112 if (!RegProcedureIsValid(hash_proc))
113 elog(ERROR, "missing support function %d(%u,%u) for index \"%s\"",
116 collation = rel->rd_indcollation[0];
117
118 return DatumGetUInt32(OidFunctionCall1Coll(hash_proc, collation, key));
119}
#define RegProcedureIsValid(p)
Definition c.h:921
regproc RegProcedure
Definition c.h:793
#define elog(elevel,...)
Definition elog.h:228
Datum OidFunctionCall1Coll(Oid functionId, Oid collation, Datum arg1)
Definition fmgr.c:1413
Oid get_opfamily_proc(Oid opfamily, Oid lefttype, Oid righttype, int16 procnum)
Definition lsyscache.c:1022
Oid * rd_opfamily
Definition rel.h:207

References DatumGetUInt32(), elog, ERROR, fb(), get_opfamily_proc(), HASHSTANDARD_PROC, OidFunctionCall1Coll(), RelationData::rd_indcollation, RelationData::rd_opfamily, RegProcedureIsValid, and RelationGetRelationName.

Referenced by _hash_first().

◆ _hash_doinsert()

void _hash_doinsert ( Relation  rel,
IndexTuple  itup,
Relation  heapRel,
bool  sorted 
)
extern

Definition at line 38 of file hashinsert.c.

39{
43 HashMetaPage metap;
46 Page page;
48 Size itemsz;
49 bool do_expand;
54
55 /*
56 * Get the hash key for the item (it's stored in the index tuple itself).
57 */
59
60 /* compute item size too */
61 itemsz = IndexTupleSize(itup);
62 itemsz = MAXALIGN(itemsz); /* be safe, PageAddItem will do this but we
63 * need to be consistent */
64
66
67 /*
68 * Read the metapage. We don't lock it yet; HashMaxItemSize() will
69 * examine pd_pagesize_version, but that can't change so we can examine it
70 * without a lock.
71 */
74
75 /*
76 * Check whether the item can fit on a hash page at all. (Eventually, we
77 * ought to try to apply TOAST methods if not.) Note that at this point,
78 * itemsz doesn't include the ItemId.
79 *
80 * XXX this is useless code if we are only storing hash keys.
81 */
82 if (itemsz > HashMaxItemSize(metapage))
85 errmsg("index row size %zu exceeds hash maximum %zu",
86 itemsz, HashMaxItemSize(metapage)),
87 errhint("Values larger than a buffer page cannot be indexed.")));
88
89 /* Lock the primary bucket page for the target bucket. */
91 &usedmetap);
93
95
96 /* remember the primary bucket buffer to release the pin on it at end. */
98
99 page = BufferGetPage(buf);
101 bucket = pageopaque->hasho_bucket;
102
103 /*
104 * If this bucket is in the process of being split, try to finish the
105 * split before inserting, because that might create room for the
106 * insertion to proceed without allocating an additional overflow page.
107 * It's only interesting to finish the split if we're trying to insert
108 * into the bucket from which we're removing tuples (the "old" bucket),
109 * not if we're trying to insert into the bucket into which tuples are
110 * being moved (the "new" bucket).
111 */
113 {
114 /* release the lock on bucket buffer, before completing the split. */
116
118 usedmetap->hashm_maxbucket,
119 usedmetap->hashm_highmask,
120 usedmetap->hashm_lowmask);
121
122 /* release the pin on old and meta buffer. retry for insert. */
123 _hash_dropbuf(rel, buf);
125 goto restart_insert;
126 }
127
128 /* Do the insertion */
129 while (PageGetFreeSpace(page) < itemsz)
130 {
131 BlockNumber nextblkno;
132
133 /*
134 * Check if current page has any DEAD tuples. If yes, delete these
135 * tuples and see if we can get a space for the new item to be
136 * inserted before moving to the next page in the bucket chain.
137 */
139 {
140
142 {
143 _hash_vacuum_one_page(rel, heapRel, metabuf, buf);
144
145 if (PageGetFreeSpace(page) >= itemsz)
146 break; /* OK, now we have enough space */
147 }
148 }
149
150 /*
151 * no space on this page; check for an overflow page
152 */
153 nextblkno = pageopaque->hasho_nextblkno;
154
155 if (BlockNumberIsValid(nextblkno))
156 {
157 /*
158 * ovfl page exists; go get it. if it doesn't have room, we'll
159 * find out next pass through the loop test above. we always
160 * release both the lock and pin if this is an overflow page, but
161 * only the lock if this is the primary bucket page, since the pin
162 * on the primary bucket must be retained throughout the scan.
163 */
164 if (buf != bucket_buf)
165 _hash_relbuf(rel, buf);
166 else
168 buf = _hash_getbuf(rel, nextblkno, HASH_WRITE, LH_OVERFLOW_PAGE);
169 page = BufferGetPage(buf);
170 }
171 else
172 {
173 /*
174 * we're at the end of the bucket chain and we haven't found a
175 * page with enough room. allocate a new overflow page.
176 */
177
178 /* release our write lock without modifying buffer */
180
181 /* chain to a new overflow page */
183 page = BufferGetPage(buf);
184
185 /* should fit now, given test above */
186 Assert(PageGetFreeSpace(page) >= itemsz);
187 }
190 Assert(pageopaque->hasho_bucket == bucket);
191 }
192
193 /*
194 * Write-lock the metapage so we can increment the tuple count. After
195 * incrementing it, check to see if it's time for a split.
196 */
198
199 /* Do the update. No ereport(ERROR) until changes are logged */
201
202 /* found page with enough space, so add the item here */
203 itup_off = _hash_pgaddtup(rel, buf, itemsz, itup, sorted);
205
206 /* metapage operations */
207 metap = HashPageGetMeta(metapage);
208 metap->hashm_ntuples += 1;
209
210 /* Make sure this stays in sync with _hash_expandtable() */
211 do_expand = metap->hashm_ntuples >
212 (double) metap->hashm_ffactor * (metap->hashm_maxbucket + 1);
213
215
216 /* XLOG stuff */
217 if (RelationNeedsWAL(rel))
218 {
220
222
225
227
229 XLogRegisterBufData(0, itup, IndexTupleSize(itup));
230
232 }
233 else
234 recptr = XLogGetFakeLSN(rel);
235
238
240
241 /* drop lock on metapage, but keep pin */
243
244 /*
245 * Release the modified page and ensure to release the pin on primary
246 * page.
247 */
248 _hash_relbuf(rel, buf);
249 if (buf != bucket_buf)
251
252 /* Attempt to split if a split is needed */
253 if (do_expand)
255
256 /* Finally drop our pin on the metapage */
258}
bool IsBufferCleanupOK(Buffer buffer)
Definition bufmgr.c:6950
Size PageGetFreeSpace(const PageData *page)
Definition bufpage.c:916
size_t Size
Definition c.h:748
#define HASH_NOLOCK
Definition hash.h:341
#define H_BUCKET_BEING_SPLIT(opaque)
Definition hash.h:91
#define HASH_METAPAGE
Definition hash.h:198
#define H_HAS_DEAD_TUPLES(opaque)
Definition hash.h:93
#define HashMaxItemSize(page)
Definition hash.h:287
#define SizeOfHashInsert
Definition hash_xlog.h:61
#define XLOG_HASH_INSERT
Definition hash_xlog.h:29
OffsetNumber _hash_pgaddtup(Relation rel, Buffer buf, Size itemsize, IndexTuple itup, bool appendtup)
Definition hashinsert.c:276
static void _hash_vacuum_one_page(Relation rel, Relation hrel, Buffer metabuf, Buffer buf)
Definition hashinsert.c:368
Buffer _hash_addovflpage(Relation rel, Buffer metabuf, Buffer buf, bool retain_pin)
Definition hashovfl.c:112
void _hash_dropbuf(Relation rel, Buffer buf)
Definition hashpage.c:277
void _hash_finish_split(Relation rel, Buffer metabuf, Buffer obuf, Bucket obucket, uint32 maxbucket, uint32 highmask, uint32 lowmask)
Definition hashpage.c:1360
Buffer _hash_getbucketbuf_from_hashkey(Relation rel, uint32 hashkey, int access, HashMetaPage *cachedmetap)
Definition hashpage.c:1565
void _hash_expandtable(Relation rel, Buffer metabuf)
Definition hashpage.c:614
static Size IndexTupleSize(const IndexTupleData *itup)
Definition itup.h:71
void CheckForSerializableConflictIn(Relation relation, const ItemPointerData *tid, BlockNumber blkno)
Definition predicate.c:4265
uint32 hashm_maxbucket
Definition hash.h:254
double hashm_ntuples
Definition hash.h:248
uint16 hashm_ffactor
Definition hash.h:249
OffsetNumber offnum
Definition hash_xlog.h:58

References _hash_addovflpage(), _hash_dropbuf(), _hash_expandtable(), _hash_finish_split(), _hash_get_indextuple_hashkey(), _hash_getbucketbuf_from_hashkey(), _hash_getbuf(), _hash_pgaddtup(), _hash_relbuf(), _hash_vacuum_one_page(), Assert, BlockNumberIsValid(), buf, BUFFER_LOCK_EXCLUSIVE, BUFFER_LOCK_UNLOCK, BufferGetBlockNumber(), BufferGetPage(), CheckForSerializableConflictIn(), END_CRIT_SECTION, ereport, errcode(), errhint(), errmsg, ERROR, fb(), H_BUCKET_BEING_SPLIT, H_HAS_DEAD_TUPLES, HASH_METAPAGE, HASH_NOLOCK, HASH_WRITE, HashMetaPageData::hashm_ffactor, HashMetaPageData::hashm_maxbucket, HashMetaPageData::hashm_ntuples, HashMaxItemSize, HashPageGetMeta, HashPageGetOpaque, IndexTupleSize(), InvalidBuffer, IsBufferCleanupOK(), LH_META_PAGE, LH_OVERFLOW_PAGE, LH_PAGE_TYPE, LockBuffer(), MarkBufferDirty(), MAXALIGN, xl_hash_insert::offnum, PageGetFreeSpace(), PageSetLSN(), REGBUF_STANDARD, RelationNeedsWAL, SizeOfHashInsert, START_CRIT_SECTION, XLOG_HASH_INSERT, XLogBeginInsert(), XLogGetFakeLSN(), XLogInsert(), XLogRegisterBufData(), XLogRegisterBuffer(), and XLogRegisterData().

Referenced by _h_indexbuild(), hashbuildCallback(), and hashinsert().

◆ _hash_dropbuf()

void _hash_dropbuf ( Relation  rel,
Buffer  buf 
)
extern

◆ _hash_dropscanbuf()

void _hash_dropscanbuf ( Relation  rel,
HashScanOpaque  so 
)
extern

Definition at line 289 of file hashpage.c.

290{
291 /* release pin we hold on primary bucket page */
292 if (BufferIsValid(so->hashso_bucket_buf) &&
293 so->hashso_bucket_buf != so->currPos.buf)
294 _hash_dropbuf(rel, so->hashso_bucket_buf);
295 so->hashso_bucket_buf = InvalidBuffer;
296
297 /* release pin we hold on primary bucket page of bucket being split */
298 if (BufferIsValid(so->hashso_split_bucket_buf) &&
299 so->hashso_split_bucket_buf != so->currPos.buf)
300 _hash_dropbuf(rel, so->hashso_split_bucket_buf);
301 so->hashso_split_bucket_buf = InvalidBuffer;
302
303 /* release any pin we still hold */
304 if (BufferIsValid(so->currPos.buf))
305 _hash_dropbuf(rel, so->currPos.buf);
306 so->currPos.buf = InvalidBuffer;
307
308 /* reset split scan */
309 so->hashso_buc_populated = false;
310 so->hashso_buc_split = false;
311}

References _hash_dropbuf(), BufferIsValid(), fb(), and InvalidBuffer.

Referenced by _hash_next(), hashendscan(), and hashrescan().

◆ _hash_expandtable()

void _hash_expandtable ( Relation  rel,
Buffer  metabuf 
)
extern

Definition at line 614 of file hashpage.c.

615{
616 HashMetaPage metap;
618 Bucket new_bucket;
624 Page opage;
625 Page npage;
631 bool metap_update_masks = false;
632 bool metap_update_splitpoint = false;
634
636
637 /*
638 * Write-lock the meta page. It used to be necessary to acquire a
639 * heavyweight lock to begin a split, but that is no longer required.
640 */
642
645
646 /*
647 * Check to see if split is still needed; someone else might have already
648 * done one while we waited for the lock.
649 *
650 * Make sure this stays in sync with _hash_doinsert()
651 */
652 if (metap->hashm_ntuples <=
653 (double) metap->hashm_ffactor * (metap->hashm_maxbucket + 1))
654 goto fail;
655
656 /*
657 * Can't split anymore if maxbucket has reached its maximum possible
658 * value.
659 *
660 * Ideally we'd allow bucket numbers up to UINT_MAX-1 (no higher because
661 * the calculation maxbucket+1 mustn't overflow). Currently we restrict
662 * to half that to prevent failure of pg_ceil_log2_32() and insufficient
663 * space in hashm_spares[]. It's moot anyway because an index with 2^32
664 * buckets would certainly overflow BlockNumber and hence
665 * _hash_alloc_buckets() would fail, but if we supported buckets smaller
666 * than a disk block then this would be an independent constraint.
667 *
668 * If you change this, see also the maximum initial number of buckets in
669 * _hash_init().
670 */
671 if (metap->hashm_maxbucket >= (uint32) 0x7FFFFFFE)
672 goto fail;
673
674 /*
675 * Determine which bucket is to be split, and attempt to take cleanup lock
676 * on the old bucket. If we can't get the lock, give up.
677 *
678 * The cleanup lock protects us not only against other backends, but
679 * against our own backend as well.
680 *
681 * The cleanup lock is mainly to protect the split from concurrent
682 * inserts. See src/backend/access/hash/README, Lock Definitions for
683 * further details. Due to this locking restriction, if there is any
684 * pending scan, the split will give up which is not good, but harmless.
685 */
686 new_bucket = metap->hashm_maxbucket + 1;
687
688 old_bucket = (new_bucket & metap->hashm_lowmask);
689
691
693 if (!buf_oblkno)
694 goto fail;
695
698
699 /*
700 * We want to finish the split from a bucket as there is no apparent
701 * benefit by not doing so and it will make the code complicated to finish
702 * the split that involves multiple buckets considering the case where new
703 * split also fails. We don't need to consider the new bucket for
704 * completing the split here as it is not possible that a re-split of new
705 * bucket starts when there is still a pending split from old bucket.
706 */
708 {
709 /*
710 * Copy bucket mapping info now; refer the comment in code below where
711 * we copy this information before calling _hash_splitbucket to see
712 * why this is okay.
713 */
714 maxbucket = metap->hashm_maxbucket;
715 highmask = metap->hashm_highmask;
716 lowmask = metap->hashm_lowmask;
717
718 /*
719 * Release the lock on metapage and old_bucket, before completing the
720 * split.
721 */
724
727
728 /* release the pin on old buffer and retry for expand. */
730
731 goto restart_expand;
732 }
733
734 /*
735 * Clean the tuples remained from the previous split. This operation
736 * requires cleanup lock and we already have one on the old bucket, so
737 * let's do it. We also don't want to allow further splits from the bucket
738 * till the garbage of previous split is cleaned. This has two
739 * advantages; first, it helps in avoiding the bloat due to garbage and
740 * second is, during cleanup of bucket, we are always sure that the
741 * garbage tuples belong to most recently split bucket. On the contrary,
742 * if we allow cleanup of bucket after meta page is updated to indicate
743 * the new split and before the actual split, the cleanup operation won't
744 * be able to decide whether the tuple has been moved to the newly created
745 * bucket and ended up deleting such tuples.
746 */
748 {
749 /*
750 * Copy bucket mapping info now; refer to the comment in code below
751 * where we copy this information before calling _hash_splitbucket to
752 * see why this is okay.
753 */
754 maxbucket = metap->hashm_maxbucket;
755 highmask = metap->hashm_highmask;
756 lowmask = metap->hashm_lowmask;
757
758 /* Release the metapage lock. */
760
763 NULL, NULL);
764
766
767 goto restart_expand;
768 }
769
770 /*
771 * There shouldn't be any active scan on new bucket.
772 *
773 * Note: it is safe to compute the new bucket's blkno here, even though we
774 * may still need to update the BUCKET_TO_BLKNO mapping. This is because
775 * the current value of hashm_spares[hashm_ovflpoint] correctly shows
776 * where we are going to put a new splitpoint's worth of buckets.
777 */
778 start_nblkno = BUCKET_TO_BLKNO(metap, new_bucket);
779
780 /*
781 * If the split point is increasing we need to allocate a new batch of
782 * bucket pages.
783 */
784 spare_ndx = _hash_spareindex(new_bucket + 1);
785 if (spare_ndx > metap->hashm_ovflpoint)
786 {
788
789 Assert(spare_ndx == metap->hashm_ovflpoint + 1);
790
791 /*
792 * We treat allocation of buckets as a separate WAL-logged action.
793 * Even if we fail after this operation, won't leak bucket pages;
794 * rather, the next split will consume this space. In any case, even
795 * without failure we don't use all the space in one split operation.
796 */
799 {
800 /* can't split due to BlockNumber overflow */
802 goto fail;
803 }
804 }
805
806 /*
807 * Physically allocate the new bucket's primary page. We want to do this
808 * before changing the metapage's mapping info, in case we can't get the
809 * disk space.
810 *
811 * XXX It doesn't make sense to call _hash_getnewbuf first, zeroing the
812 * buffer, and then only afterwards check whether we have a cleanup lock.
813 * However, since no scan can be accessing the buffer yet, any concurrent
814 * accesses will just be from processes like the bgwriter or checkpointer
815 * which don't care about its contents, so it doesn't really matter.
816 */
819 {
822 goto fail;
823 }
824
825 /*
826 * Since we are scribbling on the pages in the shared buffers, establish a
827 * critical section. Any failure in this next code leaves us with a big
828 * problem: the metapage is effectively corrupt but could get written back
829 * to disk.
830 */
832
833 /*
834 * Okay to proceed with split. Update the metapage bucket mapping info.
835 */
836 metap->hashm_maxbucket = new_bucket;
837
838 if (new_bucket > metap->hashm_highmask)
839 {
840 /* Starting a new doubling */
841 metap->hashm_lowmask = metap->hashm_highmask;
842 metap->hashm_highmask = new_bucket | metap->hashm_lowmask;
843 metap_update_masks = true;
844 }
845
846 /*
847 * If the split point is increasing we need to adjust the hashm_spares[]
848 * array and hashm_ovflpoint so that future overflow pages will be created
849 * beyond this new batch of bucket pages.
850 */
851 if (spare_ndx > metap->hashm_ovflpoint)
852 {
853 metap->hashm_spares[spare_ndx] = metap->hashm_spares[metap->hashm_ovflpoint];
854 metap->hashm_ovflpoint = spare_ndx;
856 }
857
859
860 /*
861 * Copy bucket mapping info now; this saves re-accessing the meta page
862 * inside _hash_splitbucket's inner loop. Note that once we drop the
863 * split lock, other splits could begin, so these values might be out of
864 * date before _hash_splitbucket finishes. That's okay, since all it
865 * needs is to tell which of these two buckets to map hashkeys into.
866 */
867 maxbucket = metap->hashm_maxbucket;
868 highmask = metap->hashm_highmask;
869 lowmask = metap->hashm_lowmask;
870
873
874 /*
875 * Mark the old bucket to indicate that split is in progress. (At
876 * operation end, we will clear the split-in-progress flag.) Also, for a
877 * primary bucket page, hasho_prevblkno stores the number of buckets that
878 * existed as of the last split, so we must update that value here.
879 */
880 oopaque->hasho_flag |= LH_BUCKET_BEING_SPLIT;
881 oopaque->hasho_prevblkno = maxbucket;
882
884
885 npage = BufferGetPage(buf_nblkno);
886
887 /*
888 * initialize the new bucket's primary page and mark it to indicate that
889 * split is in progress.
890 */
891 nopaque = HashPageGetOpaque(npage);
892 nopaque->hasho_prevblkno = maxbucket;
893 nopaque->hasho_nextblkno = InvalidBlockNumber;
894 nopaque->hasho_bucket = new_bucket;
896 nopaque->hasho_page_id = HASHO_PAGE_ID;
897
899
900 /* XLOG stuff */
901 if (RelationNeedsWAL(rel))
902 {
904
906 xlrec.old_bucket_flag = oopaque->hasho_flag;
907 xlrec.new_bucket_flag = nopaque->hasho_flag;
908 xlrec.flags = 0;
909
911
915
917 {
919 XLogRegisterBufData(2, &metap->hashm_lowmask, sizeof(uint32));
920 XLogRegisterBufData(2, &metap->hashm_highmask, sizeof(uint32));
921 }
922
924 {
927 sizeof(uint32));
929 &metap->hashm_spares[metap->hashm_ovflpoint],
930 sizeof(uint32));
931 }
932
934
936 }
937 else
938 recptr = XLogGetFakeLSN(rel);
939
943
945
946 /* drop lock, but keep pin */
948
949 /* Relocate records to the new bucket */
951 old_bucket, new_bucket,
954
955 /* all done, now release the pins on primary buckets. */
958
959 return;
960
961 /* Here if decide not to split or fail to acquire old bucket lock */
962fail:
963
964 /* We didn't write the metapage, so just drop lock */
966}
void hashbucketcleanup(Relation rel, Bucket cur_bucket, Buffer bucket_buf, BlockNumber bucket_blkno, BufferAccessStrategy bstrategy, uint32 maxbucket, uint32 highmask, uint32 lowmask, double *tuples_removed, double *num_index_tuples, bool split_cleanup, IndexBulkDeleteCallback callback, void *callback_state)
Definition hash.c:767
#define LH_BUCKET_BEING_POPULATED
Definition hash.h:58
#define BUCKET_TO_BLKNO(metap, B)
Definition hash.h:39
#define H_NEEDS_SPLIT_CLEANUP(opaque)
Definition hash.h:90
#define LH_BUCKET_BEING_SPLIT
Definition hash.h:59
#define XLOG_HASH_SPLIT_ALLOCATE_PAGE
Definition hash_xlog.h:31
#define SizeOfHashSplitAllocPage
Definition hash_xlog.h:100
#define XLH_SPLIT_META_UPDATE_SPLITPOINT
Definition hash_xlog.h:46
#define XLH_SPLIT_META_UPDATE_MASKS
Definition hash_xlog.h:45
Buffer _hash_getbuf_with_condlock_cleanup(Relation rel, BlockNumber blkno, int flags)
Definition hashpage.c:96
static void _hash_splitbucket(Relation rel, Buffer metabuf, Bucket obucket, Bucket nbucket, Buffer obuf, Buffer nbuf, HTAB *htab, uint32 maxbucket, uint32 highmask, uint32 lowmask)
Definition hashpage.c:1075
static bool _hash_alloc_buckets(Relation rel, BlockNumber firstblock, uint32 nblocks)
Definition hashpage.c:994
uint32 _hash_spareindex(uint32 num_bucket)
Definition hashutil.c:142
uint32 _hash_get_totalbuckets(uint32 splitpoint_phase)
Definition hashutil.c:174
uint32 hashm_lowmask
Definition hash.h:256
uint32 hashm_highmask
Definition hash.h:255

References _hash_alloc_buckets(), _hash_checkpage(), _hash_dropbuf(), _hash_finish_split(), _hash_get_totalbuckets(), _hash_getbuf_with_condlock_cleanup(), _hash_getnewbuf(), _hash_relbuf(), _hash_spareindex(), _hash_splitbucket(), Assert, BUCKET_TO_BLKNO, BUFFER_LOCK_EXCLUSIVE, BUFFER_LOCK_UNLOCK, BufferGetPage(), END_CRIT_SECTION, fb(), H_BUCKET_BEING_SPLIT, H_NEEDS_SPLIT_CLEANUP, hashbucketcleanup(), HashMetaPageData::hashm_ffactor, HashMetaPageData::hashm_highmask, HashMetaPageData::hashm_lowmask, HashMetaPageData::hashm_maxbucket, HashMetaPageData::hashm_ntuples, HashMetaPageData::hashm_ovflpoint, HashMetaPageData::hashm_spares, HASHO_PAGE_ID, HashPageGetMeta, HashPageGetOpaque, InvalidBlockNumber, IsBufferCleanupOK(), LH_BUCKET_BEING_POPULATED, LH_BUCKET_BEING_SPLIT, LH_BUCKET_PAGE, LH_META_PAGE, LockBuffer(), MAIN_FORKNUM, MarkBufferDirty(), xl_hash_split_allocate_page::new_bucket, PageSetLSN(), REGBUF_STANDARD, REGBUF_WILL_INIT, RelationNeedsWAL, SizeOfHashSplitAllocPage, START_CRIT_SECTION, XLH_SPLIT_META_UPDATE_MASKS, XLH_SPLIT_META_UPDATE_SPLITPOINT, XLOG_HASH_SPLIT_ALLOCATE_PAGE, XLogBeginInsert(), XLogGetFakeLSN(), XLogInsert(), XLogRegisterBufData(), XLogRegisterBuffer(), and XLogRegisterData().

Referenced by _hash_doinsert().

◆ _hash_finish_split()

void _hash_finish_split ( Relation  rel,
Buffer  metabuf,
Buffer  obuf,
Bucket  obucket,
uint32  maxbucket,
uint32  highmask,
uint32  lowmask 
)
extern

Definition at line 1360 of file hashpage.c.

1362{
1364 HTAB *tidhtab;
1366 Buffer nbuf;
1367 Page npage;
1372 bool found;
1373
1374 /* Initialize hash tables used to track TIDs */
1375 hash_ctl.keysize = sizeof(ItemPointerData);
1376 hash_ctl.entrysize = sizeof(ItemPointerData);
1378
1379 tidhtab =
1380 hash_create("bucket ctids",
1381 256, /* arbitrary initial size */
1382 &hash_ctl,
1384
1386
1387 /*
1388 * Scan the new bucket and build hash table of TIDs
1389 */
1390 for (;;)
1391 {
1394
1397
1398 /* remember the primary bucket buffer to acquire cleanup lock on it. */
1399 if (nblkno == bucket_nblkno)
1400 bucket_nbuf = nbuf;
1401
1402 npage = BufferGetPage(nbuf);
1404
1405 /* Scan each tuple in new page */
1410 {
1411 IndexTuple itup;
1412
1413 /* Fetch the item's TID and insert it in hash table. */
1414 itup = (IndexTuple) PageGetItem(npage,
1415 PageGetItemId(npage, noffnum));
1416
1417 (void) hash_search(tidhtab, &itup->t_tid, HASH_ENTER, &found);
1418
1419 Assert(!found);
1420 }
1421
1422 nblkno = npageopaque->hasho_nextblkno;
1423
1424 /*
1425 * release our write lock without modifying buffer and ensure to
1426 * retain the pin on primary bucket.
1427 */
1428 if (nbuf == bucket_nbuf)
1430 else
1431 _hash_relbuf(rel, nbuf);
1432
1433 /* Exit loop if no more overflow pages in new bucket */
1435 break;
1436 }
1437
1438 /*
1439 * Conditionally get the cleanup lock on old and new buckets to perform
1440 * the split operation. If we don't get the cleanup locks, silently give
1441 * up and next insertion on old bucket will try again to complete the
1442 * split.
1443 */
1445 {
1447 return;
1448 }
1450 {
1453 return;
1454 }
1455
1456 npage = BufferGetPage(bucket_nbuf);
1458 nbucket = npageopaque->hasho_bucket;
1459
1463
1466}
bool ConditionalLockBufferForCleanup(Buffer buffer)
Definition bufmgr.c:6892
void * hash_search(HTAB *hashp, const void *keyPtr, HASHACTION action, bool *foundPtr)
Definition dynahash.c:889
HTAB * hash_create(const char *tabname, int64 nelem, const HASHCTL *info, int flags)
Definition dynahash.c:360
void hash_destroy(HTAB *hashp)
Definition dynahash.c:802
#define HASH_READ
Definition hash.h:339
BlockNumber _hash_get_newblock_from_oldbucket(Relation rel, Bucket old_bucket)
Definition hashutil.c:461
@ HASH_ENTER
Definition hsearch.h:109
#define HASH_CONTEXT
Definition hsearch.h:97
#define HASH_ELEM
Definition hsearch.h:90
#define HASH_BLOBS
Definition hsearch.h:92
MemoryContext CurrentMemoryContext
Definition mcxt.c:161
#define OffsetNumberNext(offsetNumber)
Definition off.h:52
ItemPointerData t_tid
Definition itup.h:37

References _hash_dropbuf(), _hash_get_newblock_from_oldbucket(), _hash_getbuf(), _hash_relbuf(), _hash_splitbucket(), Assert, BlockNumberIsValid(), BUFFER_LOCK_UNLOCK, BufferGetPage(), ConditionalLockBufferForCleanup(), CurrentMemoryContext, fb(), FirstOffsetNumber, HASH_BLOBS, HASH_CONTEXT, hash_create(), hash_destroy(), HASH_ELEM, HASH_ENTER, HASH_READ, hash_search(), HashPageGetOpaque, InvalidBuffer, LH_BUCKET_PAGE, LH_OVERFLOW_PAGE, LockBuffer(), OffsetNumberNext, PageGetItem(), PageGetItemId(), PageGetMaxOffsetNumber(), and IndexTupleData::t_tid.

Referenced by _hash_doinsert(), and _hash_expandtable().

◆ _hash_first()

bool _hash_first ( IndexScanDesc  scan,
ScanDirection  dir 
)
extern

Definition at line 289 of file hashsearch.c.

290{
291 Relation rel = scan->indexRelation;
293 ScanKey cur;
296 Buffer buf;
297 Page page;
298 HashPageOpaque opaque;
300
302 if (scan->instrument)
303 scan->instrument->nsearches++;
304
305 /*
306 * We do not support hash scans with no index qualification, because we
307 * would have to read the whole index rather than just one bucket. That
308 * creates a whole raft of problems, since we haven't got a practical way
309 * to lock all the buckets against splits or compactions.
310 */
311 if (scan->numberOfKeys < 1)
314 errmsg("hash indexes do not support whole-index scans")));
315
316 /* There may be more than one index qual, but we hash only the first */
317 cur = &scan->keyData[0];
318
319 /* We support only single-column hash indexes */
320 Assert(cur->sk_attno == 1);
321 /* And there's only one operator strategy, too */
322 Assert(cur->sk_strategy == HTEqualStrategyNumber);
323
324 /*
325 * If the constant in the index qual is NULL, assume it cannot match any
326 * items in the index.
327 */
328 if (cur->sk_flags & SK_ISNULL)
329 return false;
330
331 /*
332 * Okay to compute the hash key. We want to do this before acquiring any
333 * locks, in case a user-defined hash function happens to be slow.
334 *
335 * If scankey operator is not a cross-type comparison, we can use the
336 * cached hash function; otherwise gotta look it up in the catalogs.
337 *
338 * We support the convention that sk_subtype == InvalidOid means the
339 * opclass input type; this is a hack to simplify life for ScanKeyInit().
340 */
341 if (cur->sk_subtype == rel->rd_opcintype[0] ||
342 cur->sk_subtype == InvalidOid)
343 hashkey = _hash_datum2hashkey(rel, cur->sk_argument);
344 else
345 hashkey = _hash_datum2hashkey_type(rel, cur->sk_argument,
346 cur->sk_subtype);
347
348 so->hashso_sk_hash = hashkey;
349
352 page = BufferGetPage(buf);
353 opaque = HashPageGetOpaque(page);
354 bucket = opaque->hasho_bucket;
355
356 so->hashso_bucket_buf = buf;
357
358 /*
359 * If a bucket split is in progress, then while scanning the bucket being
360 * populated, we need to skip tuples that were copied from bucket being
361 * split. We also need to maintain a pin on the bucket being split to
362 * ensure that split-cleanup work done by vacuum doesn't remove tuples
363 * from it till this scan is done. We need to maintain a pin on the
364 * bucket being populated to ensure that vacuum doesn't squeeze that
365 * bucket till this scan is complete; otherwise, the ordering of tuples
366 * can't be maintained during forward and backward scans. Here, we have
367 * to be cautious about locking order: first, acquire the lock on bucket
368 * being split; then, release the lock on it but not the pin; then,
369 * acquire a lock on bucket being populated and again re-verify whether
370 * the bucket split is still in progress. Acquiring the lock on bucket
371 * being split first ensures that the vacuum waits for this scan to
372 * finish.
373 */
374 if (H_BUCKET_BEING_POPULATED(opaque))
375 {
378
380
381 /*
382 * release the lock on new bucket and re-acquire it after acquiring
383 * the lock on old bucket.
384 */
386
388
389 /*
390 * remember the split bucket buffer so as to use it later for
391 * scanning.
392 */
393 so->hashso_split_bucket_buf = old_buf;
395
397 page = BufferGetPage(buf);
398 opaque = HashPageGetOpaque(page);
399 Assert(opaque->hasho_bucket == bucket);
400
401 if (H_BUCKET_BEING_POPULATED(opaque))
402 so->hashso_buc_populated = true;
403 else
404 {
405 _hash_dropbuf(rel, so->hashso_split_bucket_buf);
406 so->hashso_split_bucket_buf = InvalidBuffer;
407 }
408 }
409
410 /* If a backwards scan is requested, move to the end of the chain */
412 {
413 /*
414 * Backward scans that start during split needs to start from end of
415 * bucket being split.
416 */
417 while (BlockNumberIsValid(opaque->hasho_nextblkno) ||
418 (so->hashso_buc_populated && !so->hashso_buc_split))
419 _hash_readnext(scan, &buf, &page, &opaque);
420 }
421
422 /* remember which buffer we have pinned, if any */
423 Assert(BufferIsInvalid(so->currPos.buf));
424 so->currPos.buf = buf;
425
426 /* Now find all the tuples satisfying the qualification from a page */
427 if (!_hash_readpage(scan, &buf, dir))
428 return false;
429
430 /* OK, itemIndex says what to return */
431 currItem = &so->currPos.items[so->currPos.itemIndex];
432 scan->xs_heaptid = currItem->heapTid;
433
434 /* if we're here, _hash_readpage found a valid tuples */
435 return true;
436}
#define BufferIsInvalid(buffer)
Definition buf.h:31
@ BUFFER_LOCK_SHARE
Definition bufmgr.h:212
struct cursor * cur
Definition ecpg.c:29
#define H_BUCKET_BEING_POPULATED(opaque)
Definition hash.h:92
HashScanOpaqueData * HashScanOpaque
Definition hash.h:192
static void _hash_readnext(IndexScanDesc scan, Buffer *bufp, Page *pagep, HashPageOpaque *opaquep)
Definition hashsearch.c:132
static bool _hash_readpage(IndexScanDesc scan, Buffer *bufP, ScanDirection dir)
Definition hashsearch.c:449
BlockNumber _hash_get_oldblock_from_newbucket(Relation rel, Bucket new_bucket)
Definition hashutil.c:422
uint32 _hash_datum2hashkey_type(Relation rel, Datum key, Oid keytype)
Definition hashutil.c:102
#define pgstat_count_index_scan(rel)
Definition pgstat.h:745
#define InvalidOid
void PredicateLockPage(Relation relation, BlockNumber blkno, Snapshot snapshot)
Definition predicate.c:2528
#define ScanDirectionIsBackward(direction)
Definition sdir.h:50
#define HTEqualStrategyNumber
Definition stratnum.h:41
BlockNumber hasho_nextblkno
Definition hash.h:80
Bucket hasho_bucket
Definition hash.h:81
struct IndexScanInstrumentation * instrument
Definition relscan.h:172
ItemPointerData xs_heaptid
Definition relscan.h:185
struct SnapshotData * xs_snapshot
Definition relscan.h:151

References _hash_datum2hashkey(), _hash_datum2hashkey_type(), _hash_dropbuf(), _hash_get_oldblock_from_newbucket(), _hash_getbucketbuf_from_hashkey(), _hash_getbuf(), _hash_readnext(), _hash_readpage(), Assert, BlockNumberIsValid(), buf, BUFFER_LOCK_SHARE, BUFFER_LOCK_UNLOCK, BufferGetBlockNumber(), BufferGetPage(), BufferIsInvalid, cur, ereport, errcode(), errmsg, ERROR, fb(), H_BUCKET_BEING_POPULATED, HASH_READ, HashPageOpaqueData::hasho_bucket, HashPageOpaqueData::hasho_nextblkno, HashPageGetOpaque, HTEqualStrategyNumber, IndexScanDescData::indexRelation, IndexScanDescData::instrument, InvalidBuffer, InvalidOid, IndexScanDescData::keyData, LH_BUCKET_PAGE, LockBuffer(), IndexScanInstrumentation::nsearches, IndexScanDescData::numberOfKeys, IndexScanDescData::opaque, pgstat_count_index_scan, PredicateLockPage(), RelationData::rd_opcintype, ScanDirectionIsBackward, SK_ISNULL, IndexScanDescData::xs_heaptid, and IndexScanDescData::xs_snapshot.

Referenced by hashgetbitmap(), and hashgettuple().

◆ _hash_freeovflpage()

BlockNumber _hash_freeovflpage ( Relation  rel,
Buffer  bucketbuf,
Buffer  ovflbuf,
Buffer  wbuf,
IndexTuple *  itups,
OffsetNumber *  itup_offsets,
Size *  tups_size,
uint16  nitups,
BufferAccessStrategy  bstrategy 
)
extern

Definition at line 492 of file hashovfl.c.

496{
497 HashMetaPage metap;
501 BlockNumber prevblkno;
502 BlockNumber blkno;
503 BlockNumber nextblkno;
508 uint32 *freep;
511 bitmapbit;
515 bool update_metap = false,
516 mod_wbuf,
517 is_prim_bucket_same_wrt,
518 is_prev_bucket_same_wrt;
520
521 /* Get information from the doomed page */
526 nextblkno = ovflopaque->hasho_nextblkno;
527 prevblkno = ovflopaque->hasho_prevblkno;
529 bucket = ovflopaque->hasho_bucket;
530
531 /*
532 * Fix up the bucket chain. this is a doubly-linked list, so we must fix
533 * up the bucket chain members behind and ahead of the overflow page being
534 * deleted. Concurrency issues are avoided by using lock chaining as
535 * described atop hashbucketcleanup.
536 */
537 if (BlockNumberIsValid(prevblkno))
538 {
539 if (prevblkno == writeblkno)
540 prevbuf = wbuf;
541 else
543 prevblkno,
546 bstrategy);
547 }
548 if (BlockNumberIsValid(nextblkno))
550 nextblkno,
553 bstrategy);
554
555 /* Note: bstrategy is intentionally not used for metapage and bitmap */
556
557 /* Read the metapage so we can determine which bitmap page to use */
560
561 /* Identify which bit to set */
563
564 bitmappage = ovflbitno >> BMPG_SHIFT(metap);
565 bitmapbit = ovflbitno & BMPG_MASK(metap);
566
567 if (bitmappage >= metap->hashm_nmaps)
568 elog(ERROR, "invalid overflow bit number %u", ovflbitno);
569 blkno = metap->hashm_mapp[bitmappage];
570
571 /* Release metapage lock while we access the bitmap page */
573
574 /* read the bitmap page to clear the bitmap bit */
579
580 /* Get write-lock on metapage to update firstfree */
582
583 /* This operation needs to log multiple tuples, prepare WAL for that */
584 if (RelationNeedsWAL(rel))
586
588
589 /*
590 * we have to insert tuples on the "write" page, being careful to preserve
591 * hashkey ordering. (If we insert many tuples into the same "write" page
592 * it would be worth qsort'ing them).
593 */
594 if (nitups > 0)
595 {
598 }
599
600 /*
601 * Reinitialize the freed overflow page. Just zeroing the page won't
602 * work, because WAL replay routines expect pages to be initialized. See
603 * explanation of RBM_NORMAL mode atop XLogReadBufferExtended. We are
604 * careful to make the special space valid here so that tools like
605 * pageinspect won't get confused.
606 */
608
610
611 ovflopaque->hasho_prevblkno = InvalidBlockNumber;
612 ovflopaque->hasho_nextblkno = InvalidBlockNumber;
613 ovflopaque->hasho_bucket = InvalidBucket;
614 ovflopaque->hasho_flag = LH_UNUSED_PAGE;
615 ovflopaque->hasho_page_id = HASHO_PAGE_ID;
616
618
620 {
623
624 Assert(prevopaque->hasho_bucket == bucket);
625 prevopaque->hasho_nextblkno = nextblkno;
627 }
629 {
632
633 Assert(nextopaque->hasho_bucket == bucket);
634 nextopaque->hasho_prevblkno = prevblkno;
636 }
637
638 /* Clear the bitmap bit to indicate that this overflow page is free */
641
642 /* if this is now the first free page, update hashm_firstfree */
643 if (ovflbitno < metap->hashm_firstfree)
644 {
645 metap->hashm_firstfree = ovflbitno;
646 update_metap = true;
648 }
649
650 /* Determine which pages are modified */
651 is_prim_bucket_same_wrt = (wbuf == bucketbuf);
652 is_prev_bucket_same_wrt = (wbuf == prevbuf);
653 mod_wbuf = (nitups > 0 || is_prev_bucket_same_wrt);
654
655 /* XLOG stuff */
656 if (RelationNeedsWAL(rel))
657 {
659
660 xlrec.prevblkno = prevblkno;
661 xlrec.nextblkno = nextblkno;
662 xlrec.ntups = nitups;
663 xlrec.is_prim_bucket_same_wrt = is_prim_bucket_same_wrt;
664 xlrec.is_prev_bucket_same_wrt = is_prev_bucket_same_wrt;
665
668
669 /*
670 * bucket buffer was not changed, but still needs to be registered to
671 * ensure that we can acquire a cleanup lock on it during replay.
672 */
673 if (!is_prim_bucket_same_wrt)
674 {
676
677 XLogRegisterBuffer(0, bucketbuf, flags);
678 }
679
680 if (nitups > 0)
681 {
684 nitups * sizeof(OffsetNumber));
685 for (int i = 0; i < nitups; i++)
686 XLogRegisterBufData(1, itups[i], tups_size[i]);
687 }
688 else if (is_prim_bucket_same_wrt || is_prev_bucket_same_wrt)
689 {
691
692 /*
693 * A write buffer needs to be registered even if no tuples are
694 * added to it to ensure that we can acquire a cleanup lock on it
695 * if it is the same as primary bucket buffer or update the
696 * nextblkno if it is same as the previous bucket buffer.
697 */
698 Assert(nitups == 0);
699
701 if (!is_prev_bucket_same_wrt)
703 else
706 }
707
709
710 /*
711 * If prevpage and the writepage (block in which we are moving tuples
712 * from overflow) are same, then no need to separately register
713 * prevpage. During replay, we can directly update the nextblock in
714 * writepage.
715 */
716 if (BufferIsValid(prevbuf) && !is_prev_bucket_same_wrt)
718
721
724
725 if (update_metap)
726 {
728 XLogRegisterBufData(6, &metap->hashm_firstfree, sizeof(uint32));
729 }
730
732 }
733 else /* !RelationNeedsWAL(rel) */
734 recptr = XLogGetFakeLSN(rel);
735
736 /* Set LSN iff wbuf is modified. */
737 if (mod_wbuf)
739
741
742 if (BufferIsValid(prevbuf) && !is_prev_bucket_same_wrt)
746
748
749 if (update_metap)
751
753
754 /* release previous bucket if it is not same as write bucket */
755 if (BufferIsValid(prevbuf) && prevblkno != writeblkno)
756 _hash_relbuf(rel, prevbuf);
757
759 _hash_relbuf(rel, ovflbuf);
760
762 _hash_relbuf(rel, nextbuf);
763
764 _hash_relbuf(rel, mapbuf);
765 _hash_relbuf(rel, metabuf);
766
767 return nextblkno;
768}
#define CLRBIT(x, i)
Definition blutils.c:28
static Size BufferGetPageSize(Buffer buffer)
Definition bufmgr.h:457
uint8_t uint8
Definition c.h:681
#define PG_USED_FOR_ASSERTS_ONLY
Definition c.h:308
int32_t int32
Definition c.h:679
#define LH_UNUSED_PAGE
Definition hash.h:53
#define ISSET(A, N)
Definition hash.h:334
#define InvalidBucket
Definition hash.h:37
#define HASH_XLOG_FREE_OVFL_BUFS
Definition hash_xlog.h:22
#define XLOG_HASH_SQUEEZE_PAGE
Definition hash_xlog.h:35
#define SizeOfHashSqueezePage
Definition hash_xlog.h:168
void _hash_pgaddmultitup(Relation rel, Buffer buf, IndexTuple *itups, OffsetNumber *itup_offsets, uint16 nitups)
Definition hashinsert.c:331
uint32 _hash_ovflblkno_to_bitno(HashMetaPage metap, BlockNumber ovflblkno)
Definition hashovfl.c:62
void _hash_pageinit(Page page, Size size)
Definition hashpage.c:596
Buffer _hash_getbuf_with_strategy(Relation rel, BlockNumber blkno, int access, int flags, BufferAccessStrategy bstrategy)
Definition hashpage.c:239
BlockNumber prevblkno
Definition hash_xlog.h:156
void XLogEnsureRecordSpace(int max_block_id, int ndatas)
Definition xloginsert.c:179
#define REGBUF_NO_CHANGE
Definition xloginsert.h:37
#define REGBUF_NO_IMAGE
Definition xloginsert.h:33

References _hash_checkpage(), _hash_getbuf(), _hash_getbuf_with_strategy(), _hash_ovflblkno_to_bitno(), _hash_pageinit(), _hash_pgaddmultitup(), _hash_relbuf(), Assert, BlockNumberIsValid(), BMPG_MASK, BMPG_SHIFT, BUFFER_LOCK_EXCLUSIVE, BUFFER_LOCK_UNLOCK, BufferGetBlockNumber(), BufferGetPage(), BufferGetPageSize(), BufferIsValid(), CLRBIT, elog, END_CRIT_SECTION, ERROR, fb(), HASH_METAPAGE, HASH_READ, HASH_WRITE, HASH_XLOG_FREE_OVFL_BUFS, HashMetaPageData::hashm_firstfree, HashMetaPageData::hashm_mapp, HashMetaPageData::hashm_nmaps, HASHO_PAGE_ID, HashPageGetBitmap, HashPageGetMeta, HashPageGetOpaque, i, InvalidBlockNumber, InvalidBucket, InvalidBuffer, ISSET, LH_BITMAP_PAGE, LH_BUCKET_PAGE, LH_META_PAGE, LH_OVERFLOW_PAGE, LH_UNUSED_PAGE, LockBuffer(), MarkBufferDirty(), PageSetLSN(), PG_USED_FOR_ASSERTS_ONLY, xl_hash_squeeze_page::prevblkno, REGBUF_NO_CHANGE, REGBUF_NO_IMAGE, REGBUF_STANDARD, RelationNeedsWAL, SizeOfHashSqueezePage, START_CRIT_SECTION, XLOG_HASH_SQUEEZE_PAGE, XLogBeginInsert(), XLogEnsureRecordSpace(), XLogGetFakeLSN(), XLogInsert(), XLogRegisterBufData(), XLogRegisterBuffer(), and XLogRegisterData().

Referenced by _hash_squeezebucket().

◆ _hash_get_indextuple_hashkey()

uint32 _hash_get_indextuple_hashkey ( IndexTuple  itup)
extern

Definition at line 291 of file hashutil.c.

292{
293 char *attp;
294
295 /*
296 * We assume the hash key is the first attribute and can't be null, so
297 * this can be done crudely but very very cheaply ...
298 */
299 attp = (char *) itup + IndexInfoFindDataOffset(itup->t_info);
300 return *((uint32 *) attp);
301}
static Size IndexInfoFindDataOffset(unsigned short t_info)
Definition itup.h:112
unsigned short t_info
Definition itup.h:49

References fb(), IndexInfoFindDataOffset(), and IndexTupleData::t_info.

Referenced by _h_indexbuild(), _hash_binsearch(), _hash_binsearch_last(), _hash_doinsert(), _hash_load_qualified_items(), _hash_pgaddmultitup(), _hash_pgaddtup(), _hash_splitbucket(), hash_page_items(), and hashbucketcleanup().

◆ _hash_get_newblock_from_oldbucket()

BlockNumber _hash_get_newblock_from_oldbucket ( Relation  rel,
Bucket  old_bucket 
)
extern

Definition at line 461 of file hashutil.c.

462{
463 Bucket new_bucket;
465 HashMetaPage metap;
466 BlockNumber blkno;
467
470
472 metap->hashm_lowmask,
473 metap->hashm_maxbucket);
474 blkno = BUCKET_TO_BLKNO(metap, new_bucket);
475
476 _hash_relbuf(rel, metabuf);
477
478 return blkno;
479}
Bucket _hash_get_newbucket_from_oldbucket(Relation rel, Bucket old_bucket, uint32 lowmask, uint32 maxbucket)
Definition hashutil.c:494

References _hash_get_newbucket_from_oldbucket(), _hash_getbuf(), _hash_relbuf(), BUCKET_TO_BLKNO, BufferGetPage(), fb(), HASH_METAPAGE, HASH_READ, HashMetaPageData::hashm_lowmask, HashMetaPageData::hashm_maxbucket, HashPageGetMeta, and LH_META_PAGE.

Referenced by _hash_finish_split().

◆ _hash_get_newbucket_from_oldbucket()

Bucket _hash_get_newbucket_from_oldbucket ( Relation  rel,
Bucket  old_bucket,
uint32  lowmask,
uint32  maxbucket 
)
extern

Definition at line 494 of file hashutil.c.

496{
497 Bucket new_bucket;
498
499 new_bucket = CALC_NEW_BUCKET(old_bucket, lowmask);
500 if (new_bucket > maxbucket)
501 {
502 lowmask = lowmask >> 1;
503 new_bucket = CALC_NEW_BUCKET(old_bucket, lowmask);
504 }
505
506 return new_bucket;
507}
#define CALC_NEW_BUCKET(old_bucket, lowmask)
Definition hashutil.c:24

References CALC_NEW_BUCKET, and fb().

Referenced by _hash_get_newblock_from_oldbucket(), and hashbucketcleanup().

◆ _hash_get_oldblock_from_newbucket()

BlockNumber _hash_get_oldblock_from_newbucket ( Relation  rel,
Bucket  new_bucket 
)
extern

Definition at line 422 of file hashutil.c.

423{
425 uint32 mask;
427 HashMetaPage metap;
428 BlockNumber blkno;
429
430 /*
431 * To get the old bucket from the current bucket, we need a mask to modulo
432 * into lower half of table. This mask is stored in meta page as
433 * hashm_lowmask, but here we can't rely on the same, because we need a
434 * value of lowmask that was prevalent at the time when bucket split was
435 * started. Masking the most significant bit of new bucket would give us
436 * old bucket.
437 */
438 mask = (((uint32) 1) << pg_leftmost_one_pos32(new_bucket)) - 1;
439 old_bucket = new_bucket & mask;
440
443
444 blkno = BUCKET_TO_BLKNO(metap, old_bucket);
445
446 _hash_relbuf(rel, metabuf);
447
448 return blkno;
449}
static int pg_leftmost_one_pos32(uint32 word)
Definition pg_bitutils.h:41

References _hash_getbuf(), _hash_relbuf(), BUCKET_TO_BLKNO, BufferGetPage(), fb(), HASH_METAPAGE, HASH_READ, HashPageGetMeta, LH_META_PAGE, and pg_leftmost_one_pos32().

Referenced by _hash_first().

◆ _hash_get_totalbuckets()

uint32 _hash_get_totalbuckets ( uint32  splitpoint_phase)
extern

Definition at line 174 of file hashutil.c.

175{
179
181 return (1 << splitpoint_phase);
182
183 /* get splitpoint's group */
188
189 /* account for buckets before splitpoint_group */
190 total_buckets = (1 << (splitpoint_group - 1));
191
192 /* account for buckets within splitpoint_group */
195 HASH_SPLITPOINT_PHASE_MASK) + 1); /* from 0-based to 1-based */
199
200 return total_buckets;
201}
#define HASH_SPLITPOINT_PHASE_MASK
Definition hash.h:234
#define HASH_SPLITPOINT_PHASE_BITS
Definition hash.h:232

References fb(), HASH_SPLITPOINT_GROUPS_WITH_ONE_PHASE, HASH_SPLITPOINT_PHASE_BITS, and HASH_SPLITPOINT_PHASE_MASK.

Referenced by _hash_expandtable(), _hash_init_metabuffer(), _hash_ovflblkno_to_bitno(), and bitno_to_blkno().

◆ _hash_getbucketbuf_from_hashkey()

Buffer _hash_getbucketbuf_from_hashkey ( Relation  rel,
uint32  hashkey,
int  access,
HashMetaPage *  cachedmetap 
)
extern

Definition at line 1565 of file hashpage.c.

1567{
1568 HashMetaPage metap;
1569 Buffer buf;
1571 Page page;
1572 Bucket bucket;
1573 BlockNumber blkno;
1574 HashPageOpaque opaque;
1575
1576 /* We read from target bucket buffer, hence locking is must. */
1578
1579 metap = _hash_getcachedmetap(rel, &metabuf, false);
1580 Assert(metap != NULL);
1581
1582 /*
1583 * Loop until we get a lock on the correct target bucket.
1584 */
1585 for (;;)
1586 {
1587 /*
1588 * Compute the target bucket number, and convert to block number.
1589 */
1591 metap->hashm_maxbucket,
1592 metap->hashm_highmask,
1593 metap->hashm_lowmask);
1594
1595 blkno = BUCKET_TO_BLKNO(metap, bucket);
1596
1597 /* Fetch the primary bucket page for the bucket */
1598 buf = _hash_getbuf(rel, blkno, access, LH_BUCKET_PAGE);
1599 page = BufferGetPage(buf);
1600 opaque = HashPageGetOpaque(page);
1601 Assert(opaque->hasho_bucket == bucket);
1603
1604 /*
1605 * If this bucket hasn't been split, we're done.
1606 */
1607 if (opaque->hasho_prevblkno <= metap->hashm_maxbucket)
1608 break;
1609
1610 /* Drop lock on this buffer, update cached metapage, and retry. */
1611 _hash_relbuf(rel, buf);
1612 metap = _hash_getcachedmetap(rel, &metabuf, true);
1613 Assert(metap != NULL);
1614 }
1615
1617 _hash_dropbuf(rel, metabuf);
1618
1619 if (cachedmetap)
1620 *cachedmetap = metap;
1621
1622 return buf;
1623}
HashMetaPage _hash_getcachedmetap(Relation rel, Buffer *metabuf, bool force_refresh)
Definition hashpage.c:1507
short access
BlockNumber hasho_prevblkno
Definition hash.h:79

References _hash_dropbuf(), _hash_getbuf(), _hash_getcachedmetap(), _hash_hashkey2bucket(), _hash_relbuf(), Assert, BUCKET_TO_BLKNO, buf, BufferGetPage(), BufferIsValid(), fb(), HASH_READ, HASH_WRITE, HashMetaPageData::hashm_highmask, HashMetaPageData::hashm_lowmask, HashMetaPageData::hashm_maxbucket, HashPageOpaqueData::hasho_bucket, HashPageOpaqueData::hasho_prevblkno, HashPageGetOpaque, InvalidBlockNumber, InvalidBuffer, and LH_BUCKET_PAGE.

Referenced by _hash_doinsert(), and _hash_first().

◆ _hash_getbuf()

Buffer _hash_getbuf ( Relation  rel,
BlockNumber  blkno,
int  access,
int  flags 
)
extern

Definition at line 70 of file hashpage.c.

71{
72 Buffer buf;
73
74 if (blkno == P_NEW)
75 elog(ERROR, "hash AM does not use P_NEW");
76
77 buf = ReadBuffer(rel, blkno);
78
79 if (access != HASH_NOLOCK)
81
82 /* ref count and lock type are correct */
83
84 _hash_checkpage(rel, buf, flags);
85
86 return buf;
87}
Buffer ReadBuffer(Relation reln, BlockNumber blockNum)
Definition bufmgr.c:879
#define P_NEW
Definition bufmgr.h:200

References _hash_checkpage(), buf, elog, ERROR, HASH_NOLOCK, LockBuffer(), P_NEW, and ReadBuffer().

Referenced by _hash_addovflpage(), _hash_doinsert(), _hash_finish_split(), _hash_first(), _hash_freeovflpage(), _hash_get_newblock_from_oldbucket(), _hash_get_oldblock_from_newbucket(), _hash_getbucketbuf_from_hashkey(), _hash_getcachedmetap(), _hash_kill_items(), _hash_next(), _hash_readnext(), _hash_readprev(), _hash_splitbucket(), hash_bitmap_info(), hashbulkdelete(), and pgstathashindex().

◆ _hash_getbuf_with_condlock_cleanup()

Buffer _hash_getbuf_with_condlock_cleanup ( Relation  rel,
BlockNumber  blkno,
int  flags 
)
extern

Definition at line 96 of file hashpage.c.

97{
98 Buffer buf;
99
100 if (blkno == P_NEW)
101 elog(ERROR, "hash AM does not use P_NEW");
102
103 buf = ReadBuffer(rel, blkno);
104
106 {
108 return InvalidBuffer;
109 }
110
111 /* ref count and lock type are correct */
112
113 _hash_checkpage(rel, buf, flags);
114
115 return buf;
116}

References _hash_checkpage(), buf, ConditionalLockBufferForCleanup(), elog, ERROR, InvalidBuffer, P_NEW, ReadBuffer(), and ReleaseBuffer().

Referenced by _hash_expandtable().

◆ _hash_getbuf_with_strategy()

Buffer _hash_getbuf_with_strategy ( Relation  rel,
BlockNumber  blkno,
int  access,
int  flags,
BufferAccessStrategy  bstrategy 
)
extern

Definition at line 239 of file hashpage.c.

242{
243 Buffer buf;
244
245 if (blkno == P_NEW)
246 elog(ERROR, "hash AM does not use P_NEW");
247
248 buf = ReadBufferExtended(rel, MAIN_FORKNUM, blkno, RBM_NORMAL, bstrategy);
249
250 if (access != HASH_NOLOCK)
252
253 /* ref count and lock type are correct */
254
255 _hash_checkpage(rel, buf, flags);
256
257 return buf;
258}
Buffer ReadBufferExtended(Relation reln, ForkNumber forkNum, BlockNumber blockNum, ReadBufferMode mode, BufferAccessStrategy strategy)
Definition bufmgr.c:926
@ RBM_NORMAL
Definition bufmgr.h:46

References _hash_checkpage(), buf, elog, ERROR, HASH_NOLOCK, LockBuffer(), MAIN_FORKNUM, P_NEW, RBM_NORMAL, and ReadBufferExtended().

Referenced by _hash_freeovflpage(), _hash_squeezebucket(), and hashbucketcleanup().

◆ _hash_getcachedmetap()

HashMetaPage _hash_getcachedmetap ( Relation  rel,
Buffer *  metabuf,
bool  force_refresh 
)
extern

Definition at line 1507 of file hashpage.c.

1508{
1509 Page page;
1510
1511 Assert(metabuf);
1512 if (force_refresh || rel->rd_amcache == NULL)
1513 {
1514 char *cache = NULL;
1515
1516 /*
1517 * It's important that we don't set rd_amcache to an invalid value.
1518 * Either MemoryContextAlloc or _hash_getbuf could fail, so don't
1519 * install a pointer to the newly-allocated storage in the actual
1520 * relcache entry until both have succeeded.
1521 */
1522 if (rel->rd_amcache == NULL)
1523 cache = MemoryContextAlloc(rel->rd_indexcxt,
1524 sizeof(HashMetaPageData));
1525
1526 /* Read the metapage. */
1527 if (BufferIsValid(*metabuf))
1529 else
1531 LH_META_PAGE);
1532 page = BufferGetPage(*metabuf);
1533
1534 /* Populate the cache. */
1535 if (rel->rd_amcache == NULL)
1536 rel->rd_amcache = cache;
1537 memcpy(rel->rd_amcache, HashPageGetMeta(page),
1538 sizeof(HashMetaPageData));
1539
1540 /* Release metapage lock, but keep the pin. */
1542 }
1543
1544 return (HashMetaPage) rel->rd_amcache;
1545}
memcpy(sums, checksumBaseOffsets, sizeof(checksumBaseOffsets))
void * MemoryContextAlloc(MemoryContext context, Size size)
Definition mcxt.c:1235
void * rd_amcache
Definition rel.h:229
MemoryContext rd_indexcxt
Definition rel.h:204

References _hash_getbuf(), Assert, BUFFER_LOCK_SHARE, BUFFER_LOCK_UNLOCK, BufferGetPage(), BufferIsValid(), fb(), HASH_METAPAGE, HASH_READ, HashPageGetMeta, LH_META_PAGE, LockBuffer(), memcpy(), MemoryContextAlloc(), RelationData::rd_amcache, and RelationData::rd_indexcxt.

Referenced by _hash_getbucketbuf_from_hashkey(), and hashbulkdelete().

◆ _hash_getinitbuf()

Buffer _hash_getinitbuf ( Relation  rel,
BlockNumber  blkno 
)
extern

Definition at line 135 of file hashpage.c.

136{
137 Buffer buf;
138
139 if (blkno == P_NEW)
140 elog(ERROR, "hash AM does not use P_NEW");
141
143 NULL);
144
145 /* ref count and lock type are correct */
146
147 /* initialize the page */
149
150 return buf;
151}
@ RBM_ZERO_AND_LOCK
Definition bufmgr.h:47

References _hash_pageinit(), buf, BufferGetPage(), BufferGetPageSize(), elog, ERROR, fb(), MAIN_FORKNUM, P_NEW, RBM_ZERO_AND_LOCK, and ReadBufferExtended().

Referenced by _hash_addovflpage().

◆ _hash_getnewbuf()

Buffer _hash_getnewbuf ( Relation  rel,
BlockNumber  blkno,
ForkNumber  forkNum 
)
extern

Definition at line 198 of file hashpage.c.

199{
200 BlockNumber nblocks = RelationGetNumberOfBlocksInFork(rel, forkNum);
201 Buffer buf;
202
203 if (blkno == P_NEW)
204 elog(ERROR, "hash AM does not use P_NEW");
205 if (blkno > nblocks)
206 elog(ERROR, "access to noncontiguous page in hash index \"%s\"",
208
209 /* smgr insists we explicitly extend the relation */
210 if (blkno == nblocks)
211 {
212 buf = ExtendBufferedRel(BMR_REL(rel), forkNum, NULL,
214 if (BufferGetBlockNumber(buf) != blkno)
215 elog(ERROR, "unexpected hash relation size: %u, should be %u",
216 BufferGetBlockNumber(buf), blkno);
217 }
218 else
219 {
220 buf = ReadBufferExtended(rel, forkNum, blkno, RBM_ZERO_AND_LOCK,
221 NULL);
222 }
223
224 /* ref count and lock type are correct */
225
226 /* initialize the page */
228
229 return buf;
230}
Buffer ExtendBufferedRel(BufferManagerRelation bmr, ForkNumber forkNum, BufferAccessStrategy strategy, uint32 flags)
Definition bufmgr.c:970
BlockNumber RelationGetNumberOfBlocksInFork(Relation relation, ForkNumber forkNum)
Definition bufmgr.c:4668
@ EB_SKIP_EXTENSION_LOCK
Definition bufmgr.h:75
@ EB_LOCK_FIRST
Definition bufmgr.h:87
#define BMR_REL(p_rel)
Definition bufmgr.h:114

References _hash_pageinit(), BMR_REL, buf, BufferGetBlockNumber(), BufferGetPage(), BufferGetPageSize(), EB_LOCK_FIRST, EB_SKIP_EXTENSION_LOCK, elog, ERROR, ExtendBufferedRel(), fb(), P_NEW, RBM_ZERO_AND_LOCK, ReadBufferExtended(), RelationGetNumberOfBlocksInFork(), and RelationGetRelationName.

Referenced by _hash_addovflpage(), _hash_expandtable(), and _hash_init().

◆ _hash_hashkey2bucket()

Bucket _hash_hashkey2bucket ( uint32  hashkey,
uint32  maxbucket,
uint32  highmask,
uint32  lowmask 
)
extern

Definition at line 125 of file hashutil.c.

127{
129
131 if (bucket > maxbucket)
133
134 return bucket;
135}

References fb().

Referenced by _h_indexbuild(), _hash_getbucketbuf_from_hashkey(), _hash_splitbucket(), comparetup_index_hash(), and hashbucketcleanup().

◆ _hash_init()

uint32 _hash_init ( Relation  rel,
double  num_tuples,
ForkNumber  forkNum 
)
extern

Definition at line 327 of file hashpage.c.

328{
330 Buffer buf;
332 Page pg;
333 HashMetaPage metap;
334 RegProcedure procid;
337 int32 ffactor;
339 uint32 i;
340 bool use_wal;
341
342 /* safety check */
343 if (RelationGetNumberOfBlocksInFork(rel, forkNum) != 0)
344 elog(ERROR, "cannot initialize non-empty hash index \"%s\"",
346
347 /*
348 * WAL log creation of pages if the relation is persistent, or this is the
349 * init fork. Init forks for unlogged relations always need to be WAL
350 * logged.
351 */
352 use_wal = RelationNeedsWAL(rel) || forkNum == INIT_FORKNUM;
353
354 /*
355 * Determine the target fill factor (in tuples per bucket) for this index.
356 * The idea is to make the fill factor correspond to pages about as full
357 * as the user-settable fillfactor parameter says. We can compute it
358 * exactly since the index datatype (i.e. uint32 hash key) is fixed-width.
359 */
360 data_width = sizeof(uint32);
362 sizeof(ItemIdData); /* include the line pointer */
363 ffactor = HashGetTargetPageUsage(rel) / item_width;
364 /* keep to a sane range */
365 if (ffactor < 10)
366 ffactor = 10;
367
368 procid = index_getprocid(rel, 1, HASHSTANDARD_PROC);
369
370 /*
371 * We initialize the metapage, the first N bucket pages, and the first
372 * bitmap page in sequence, using _hash_getnewbuf to cause smgrextend()
373 * calls to occur. This ensures that the smgr level has the right idea of
374 * the physical index length.
375 *
376 * Critical section not required, because on error the creation of the
377 * whole relation will be rolled back.
378 */
379 metabuf = _hash_getnewbuf(rel, HASH_METAPAGE, forkNum);
380 _hash_init_metabuffer(metabuf, num_tuples, procid, ffactor, false);
382
384 metap = HashPageGetMeta(pg);
385
386 /* XLOG stuff */
387 if (use_wal)
388 {
391
392 xlrec.num_tuples = num_tuples;
393 xlrec.procid = metap->hashm_procid;
394 xlrec.ffactor = metap->hashm_ffactor;
395
399
401
403 }
404
405 num_buckets = metap->hashm_maxbucket + 1;
406
407 /*
408 * Release buffer lock on the metapage while we initialize buckets.
409 * Otherwise, we'll be in interrupt holdoff and the CHECK_FOR_INTERRUPTS
410 * won't accomplish anything. It's a bad idea to hold buffer locks for
411 * long intervals in any case, since that can block the bgwriter.
412 */
414
415 /*
416 * Initialize and WAL Log the first N buckets
417 */
418 for (i = 0; i < num_buckets; i++)
419 {
420 BlockNumber blkno;
421
422 /* Allow interrupts, in case N is huge */
424
425 blkno = BUCKET_TO_BLKNO(metap, i);
426 buf = _hash_getnewbuf(rel, blkno, forkNum);
429
430 if (use_wal)
432 forkNum,
433 blkno,
435 true);
436 _hash_relbuf(rel, buf);
437 }
438
439 /* Now reacquire buffer lock on metapage */
441
442 /*
443 * Initialize bitmap page
444 */
445 bitmapbuf = _hash_getnewbuf(rel, num_buckets + 1, forkNum);
448
449 /* add the new bitmap page to the metapage's list of bitmaps */
450 /* metapage already has a write lock */
451 if (metap->hashm_nmaps >= HASH_MAX_BITMAPS)
454 errmsg("out of overflow pages in hash index \"%s\"",
456
457 metap->hashm_mapp[metap->hashm_nmaps] = num_buckets + 1;
458
459 metap->hashm_nmaps++;
461
462 /* XLOG stuff */
463 if (use_wal)
464 {
467
468 xlrec.bmsize = metap->hashm_bmsize;
469
473
474 /*
475 * This is safe only because nobody else can be modifying the index at
476 * this stage; it's only visible to the transaction that is creating
477 * it.
478 */
480
482
485 }
486
487 /* all done */
489 _hash_relbuf(rel, metabuf);
490
491 return num_buckets;
492}
#define HashGetTargetPageUsage(relation)
Definition hash.h:281
#define SizeOfHashInitBitmapPage
Definition hash_xlog.h:234
#define XLOG_HASH_INIT_BITMAP_PAGE
Definition hash_xlog.h:28
#define XLOG_HASH_INIT_META_PAGE
Definition hash_xlog.h:27
#define SizeOfHashInitMetaPage
Definition hash_xlog.h:218
void _hash_initbuf(Buffer buf, uint32 max_bucket, uint32 num_bucket, uint32 flag, bool initpage)
Definition hashpage.c:157
void _hash_init_metabuffer(Buffer buf, double num_tuples, RegProcedure procid, uint16 ffactor, bool initpage)
Definition hashpage.c:498
RegProcedure index_getprocid(Relation irel, AttrNumber attnum, uint16 procnum)
Definition indexam.c:851
@ INIT_FORKNUM
Definition relpath.h:61
RegProcedure hashm_procid
Definition hash.h:261
RelFileLocator rd_locator
Definition rel.h:57
XLogRecPtr log_newpage(RelFileLocator *rlocator, ForkNumber forknum, BlockNumber blkno, Page page, bool page_std)

References _hash_getnewbuf(), _hash_init_metabuffer(), _hash_initbitmapbuffer(), _hash_initbuf(), _hash_relbuf(), xl_hash_init_bitmap_page::bmsize, BUCKET_TO_BLKNO, buf, BUFFER_LOCK_EXCLUSIVE, BUFFER_LOCK_UNLOCK, BufferGetPage(), CHECK_FOR_INTERRUPTS, elog, ereport, errcode(), errmsg, ERROR, fb(), HASH_MAX_BITMAPS, HASH_METAPAGE, HashGetTargetPageUsage, HashMetaPageData::hashm_bmsize, HashMetaPageData::hashm_ffactor, HashMetaPageData::hashm_mapp, HashMetaPageData::hashm_maxbucket, HashMetaPageData::hashm_nmaps, HashMetaPageData::hashm_procid, HashPageGetMeta, HASHSTANDARD_PROC, i, index_getprocid(), INIT_FORKNUM, LH_BUCKET_PAGE, LockBuffer(), log_newpage(), MarkBufferDirty(), MAXALIGN, xl_hash_init_meta_page::num_tuples, PageSetLSN(), RelationData::rd_locator, REGBUF_STANDARD, REGBUF_WILL_INIT, RelationGetNumberOfBlocksInFork(), RelationGetRelationName, RelationNeedsWAL, SizeOfHashInitBitmapPage, SizeOfHashInitMetaPage, XLOG_HASH_INIT_BITMAP_PAGE, XLOG_HASH_INIT_META_PAGE, XLogBeginInsert(), XLogInsert(), XLogRegisterBuffer(), and XLogRegisterData().

Referenced by hashbuild(), and hashbuildempty().

◆ _hash_init_metabuffer()

void _hash_init_metabuffer ( Buffer  buf,
double  num_tuples,
RegProcedure  procid,
uint16  ffactor,
bool  initpage 
)
extern

Definition at line 498 of file hashpage.c.

500{
501 HashMetaPage metap;
503 Page page;
504 double dnumbuckets;
508
509 /*
510 * Choose the number of initial bucket pages to match the fill factor
511 * given the estimated number of tuples. We round up the result to the
512 * total number of buckets which has to be allocated before using its
513 * hashm_spares element. However always force at least 2 bucket pages. The
514 * upper limit is determined by considerations explained in
515 * _hash_expandtable().
516 */
517 dnumbuckets = num_tuples / ffactor;
518 if (dnumbuckets <= 2.0)
519 num_buckets = 2;
520 else if (dnumbuckets >= (double) 0x40000000)
521 num_buckets = 0x40000000;
522 else
524
527
528 page = BufferGetPage(buf);
529 if (initpage)
531
533 pageopaque->hasho_prevblkno = InvalidBlockNumber;
534 pageopaque->hasho_nextblkno = InvalidBlockNumber;
535 pageopaque->hasho_bucket = InvalidBucket;
536 pageopaque->hasho_flag = LH_META_PAGE;
537 pageopaque->hasho_page_id = HASHO_PAGE_ID;
538
539 metap = HashPageGetMeta(page);
540
541 metap->hashm_magic = HASH_MAGIC;
543 metap->hashm_ntuples = 0;
544 metap->hashm_nmaps = 0;
545 metap->hashm_ffactor = ffactor;
546 metap->hashm_bsize = HashGetMaxBitmapSize(page);
547
548 /* find largest bitmap array size that will fit in page size */
550 Assert(lshift > 0);
551 metap->hashm_bmsize = 1 << lshift;
553 Assert((1 << BMPG_SHIFT(metap)) == (BMPG_MASK(metap) + 1));
554
555 /*
556 * Label the index with its primary hash support function's OID. This is
557 * pretty useless for normal operation (in fact, hashm_procid is not used
558 * anywhere), but it might be handy for forensic purposes so we keep it.
559 */
560 metap->hashm_procid = procid;
561
562 /*
563 * We initialize the index with N buckets, 0 .. N-1, occupying physical
564 * blocks 1 to N. The first freespace bitmap page is in block N+1.
565 */
566 metap->hashm_maxbucket = num_buckets - 1;
567
568 /*
569 * Set highmask as next immediate ((2 ^ x) - 1), which should be
570 * sufficient to cover num_buckets.
571 */
573 metap->hashm_lowmask = (metap->hashm_highmask >> 1);
574
575 MemSet(metap->hashm_spares, 0, sizeof(metap->hashm_spares));
576 MemSet(metap->hashm_mapp, 0, sizeof(metap->hashm_mapp));
577
578 /* Set up mapping for one spare page after the initial splitpoints */
579 metap->hashm_spares[spare_index] = 1;
581 metap->hashm_firstfree = 0;
582
583 /*
584 * Set pd_lower just past the end of the metadata. This is essential,
585 * because without doing so, metadata will be lost if xlog.c compresses
586 * the page.
587 */
588 ((PageHeader) page)->pd_lower =
589 ((char *) metap + sizeof(HashMetaPageData)) - (char *) page;
590}
PageHeaderData * PageHeader
Definition bufpage.h:199
#define MemSet(start, val, len)
Definition c.h:1147
#define HASH_MAX_SPLITPOINTS
Definition hash.h:239
#define BYTE_TO_BIT
Definition hash.h:301
#define HashGetMaxBitmapSize(page)
Definition hash.h:319
uint16 hashm_bsize
Definition hash.h:250
uint16 hashm_bmshift
Definition hash.h:253

References _hash_get_totalbuckets(), _hash_pageinit(), _hash_spareindex(), Assert, BMPG_MASK, BMPG_SHIFT, buf, BufferGetPage(), BufferGetPageSize(), BYTE_TO_BIT, fb(), HASH_MAGIC, HASH_MAX_SPLITPOINTS, HASH_VERSION, HashGetMaxBitmapSize, HashMetaPageData::hashm_bmshift, HashMetaPageData::hashm_bmsize, HashMetaPageData::hashm_bsize, HashMetaPageData::hashm_ffactor, HashMetaPageData::hashm_firstfree, HashMetaPageData::hashm_highmask, HashMetaPageData::hashm_lowmask, HashMetaPageData::hashm_magic, HashMetaPageData::hashm_mapp, HashMetaPageData::hashm_maxbucket, HashMetaPageData::hashm_nmaps, HashMetaPageData::hashm_ntuples, HashMetaPageData::hashm_ovflpoint, HashMetaPageData::hashm_procid, HashMetaPageData::hashm_spares, HashMetaPageData::hashm_version, HASHO_PAGE_ID, HashPageGetMeta, HashPageGetOpaque, InvalidBlockNumber, InvalidBucket, LH_META_PAGE, MemSet, pg_leftmost_one_pos32(), and pg_nextpower2_32().

Referenced by _hash_init(), and hash_xlog_init_meta_page().

◆ _hash_initbitmapbuffer()

void _hash_initbitmapbuffer ( Buffer  buf,
uint16  bmsize,
bool  initpage 
)
extern

Definition at line 778 of file hashovfl.c.

779{
780 Page pg;
782 uint32 *freep;
783
785
786 /* initialize the page */
787 if (initpage)
789
790 /* initialize the page's special space */
791 op = HashPageGetOpaque(pg);
797
798 /* set all of the bits to 1 */
800 memset(freep, 0xFF, bmsize);
801
802 /*
803 * Set pd_lower just past the end of the bitmap page data. We could even
804 * set pd_lower equal to pd_upper, but this is more precise and makes the
805 * page look compressible to xlog.c.
806 */
807 ((PageHeader) pg)->pd_lower = ((char *) freep + bmsize) - (char *) pg;
808}
uint16 hasho_page_id
Definition hash.h:83

References _hash_pageinit(), buf, BufferGetPage(), BufferGetPageSize(), fb(), HashPageOpaqueData::hasho_bucket, HashPageOpaqueData::hasho_flag, HashPageOpaqueData::hasho_nextblkno, HashPageOpaqueData::hasho_page_id, HASHO_PAGE_ID, HashPageOpaqueData::hasho_prevblkno, HashPageGetBitmap, HashPageGetOpaque, InvalidBlockNumber, InvalidBucket, and LH_BITMAP_PAGE.

Referenced by _hash_addovflpage(), _hash_init(), hash_xlog_add_ovfl_page(), and hash_xlog_init_bitmap_page().

◆ _hash_initbuf()

void _hash_initbuf ( Buffer  buf,
uint32  max_bucket,
uint32  num_bucket,
uint32  flag,
bool  initpage 
)
extern

Definition at line 157 of file hashpage.c.

159{
161 Page page;
162
163 page = BufferGetPage(buf);
164
165 /* initialize the page */
166 if (initpage)
168
170
171 /*
172 * Set hasho_prevblkno with current hashm_maxbucket. This value will be
173 * used to validate cached HashMetaPageData. See
174 * _hash_getbucketbuf_from_hashkey().
175 */
176 pageopaque->hasho_prevblkno = max_bucket;
177 pageopaque->hasho_nextblkno = InvalidBlockNumber;
178 pageopaque->hasho_bucket = num_bucket;
179 pageopaque->hasho_flag = flag;
180 pageopaque->hasho_page_id = HASHO_PAGE_ID;
181}
char * flag(int b)
Definition test-ctype.c:33

References _hash_pageinit(), buf, BufferGetPage(), BufferGetPageSize(), fb(), flag(), HASHO_PAGE_ID, HashPageGetOpaque, and InvalidBlockNumber.

Referenced by _hash_init(), hash_xlog_add_ovfl_page(), and hash_xlog_split_allocate_page().

◆ _hash_kill_items()

void _hash_kill_items ( IndexScanDesc  scan)
extern

Definition at line 536 of file hashutil.c.

537{
539 Relation rel = scan->indexRelation;
540 BlockNumber blkno;
541 Buffer buf;
542 Page page;
543 HashPageOpaque opaque;
544 OffsetNumber offnum,
545 maxoff;
546 int numKilled = so->numKilled;
547 int i;
548 bool killedsomething = false;
549 bool havePin = false;
550
551 Assert(so->numKilled > 0);
552 Assert(so->killedItems != NULL);
553 Assert(HashScanPosIsValid(so->currPos));
554
555 /*
556 * Always reset the scan state, so we don't look for same items on other
557 * pages.
558 */
559 so->numKilled = 0;
560
561 blkno = so->currPos.currPage;
562 if (HashScanPosIsPinned(so->currPos))
563 {
564 /*
565 * We already have pin on this buffer, so, all we need to do is
566 * acquire lock on it.
567 */
568 havePin = true;
569 buf = so->currPos.buf;
571 }
572 else
574
575 page = BufferGetPage(buf);
576 opaque = HashPageGetOpaque(page);
577 maxoff = PageGetMaxOffsetNumber(page);
578
579 for (i = 0; i < numKilled; i++)
580 {
581 int itemIndex = so->killedItems[i];
582 HashScanPosItem *currItem = &so->currPos.items[itemIndex];
583
584 offnum = currItem->indexOffset;
585
586 Assert(itemIndex >= so->currPos.firstItem &&
587 itemIndex <= so->currPos.lastItem);
588
589 while (offnum <= maxoff)
590 {
591 ItemId iid = PageGetItemId(page, offnum);
593
594 if (ItemPointerEquals(&ituple->t_tid, &currItem->heapTid))
595 {
596 if (!killedsomething)
597 {
598 /*
599 * Use the hint bit infrastructure to check if we can
600 * update the page while just holding a share lock. If we
601 * are not allowed, there's no point continuing.
602 */
604 goto unlock_page;
605 }
606
607 /* found the item */
609 killedsomething = true;
610 break; /* out of inner search loop */
611 }
612 offnum = OffsetNumberNext(offnum);
613 }
614 }
615
616 /*
617 * Since this can be redone later if needed, mark as dirty hint. Whenever
618 * we mark anything LP_DEAD, we also set the page's
619 * LH_PAGE_HAS_DEAD_TUPLES flag, which is likewise just a hint.
620 */
621 if (killedsomething)
622 {
624 BufferFinishSetHintBits(buf, true, true);
625 }
626
628 if (havePin)
629 LockBuffer(so->currPos.buf, BUFFER_LOCK_UNLOCK);
630 else
631 _hash_relbuf(rel, buf);
632}
void BufferFinishSetHintBits(Buffer buffer, bool mark_dirty, bool buffer_std)
Definition bufmgr.c:7119
bool BufferBeginSetHintBits(Buffer buffer)
Definition bufmgr.c:7091
#define HashScanPosIsPinned(scanpos)
Definition hash.h:130
#define HashScanPosIsValid(scanpos)
Definition hash.h:137
#define LH_PAGE_HAS_DEAD_TUPLES
Definition hash.h:61
#define ItemIdMarkDead(itemId)
Definition itemid.h:179
bool ItemPointerEquals(const ItemPointerData *pointer1, const ItemPointerData *pointer2)
Definition itemptr.c:35
OffsetNumber indexOffset
Definition hash.h:106

References _hash_getbuf(), _hash_relbuf(), Assert, buf, BUFFER_LOCK_SHARE, BUFFER_LOCK_UNLOCK, BufferBeginSetHintBits(), BufferFinishSetHintBits(), BufferGetPage(), fb(), HASH_READ, HashPageOpaqueData::hasho_flag, HashPageGetOpaque, HashScanPosIsPinned, HashScanPosIsValid, i, HashScanPosItem::indexOffset, IndexScanDescData::indexRelation, ItemIdMarkDead, ItemPointerEquals(), LH_OVERFLOW_PAGE, LH_PAGE_HAS_DEAD_TUPLES, LockBuffer(), OffsetNumberNext, IndexScanDescData::opaque, PageGetItem(), PageGetItemId(), and PageGetMaxOffsetNumber().

Referenced by _hash_next(), _hash_readpage(), hashendscan(), and hashrescan().

◆ _hash_next()

bool _hash_next ( IndexScanDesc  scan,
ScanDirection  dir 
)
extern

Definition at line 49 of file hashsearch.c.

50{
51 Relation rel = scan->indexRelation;
54 BlockNumber blkno;
55 Buffer buf;
56 bool end_of_scan = false;
57
58 /*
59 * Advance to the next tuple on the current page; or if done, try to read
60 * data from the next or previous page based on the scan direction. Before
61 * moving to the next or previous page make sure that we deal with all the
62 * killed items.
63 */
65 {
66 if (++so->currPos.itemIndex > so->currPos.lastItem)
67 {
68 if (so->numKilled > 0)
69 _hash_kill_items(scan);
70
71 blkno = so->currPos.nextPage;
72 if (BlockNumberIsValid(blkno))
73 {
75 if (!_hash_readpage(scan, &buf, dir))
76 end_of_scan = true;
77 }
78 else
79 end_of_scan = true;
80 }
81 }
82 else
83 {
84 if (--so->currPos.itemIndex < so->currPos.firstItem)
85 {
86 if (so->numKilled > 0)
87 _hash_kill_items(scan);
88
89 blkno = so->currPos.prevPage;
90 if (BlockNumberIsValid(blkno))
91 {
92 buf = _hash_getbuf(rel, blkno, HASH_READ,
94
95 /*
96 * We always maintain the pin on bucket page for whole scan
97 * operation, so releasing the additional pin we have acquired
98 * here.
99 */
100 if (buf == so->hashso_bucket_buf ||
101 buf == so->hashso_split_bucket_buf)
102 _hash_dropbuf(rel, buf);
103
104 if (!_hash_readpage(scan, &buf, dir))
105 end_of_scan = true;
106 }
107 else
108 end_of_scan = true;
109 }
110 }
111
112 if (end_of_scan)
113 {
114 _hash_dropscanbuf(rel, so);
115 HashScanPosInvalidate(so->currPos);
116 return false;
117 }
118
119 /* OK, itemIndex says what to return */
120 currItem = &so->currPos.items[so->currPos.itemIndex];
121 scan->xs_heaptid = currItem->heapTid;
122
123 return true;
124}
#define HashScanPosInvalidate(scanpos)
Definition hash.h:144
void _hash_dropscanbuf(Relation rel, HashScanOpaque so)
Definition hashpage.c:289
void _hash_kill_items(IndexScanDesc scan)
Definition hashutil.c:536
#define ScanDirectionIsForward(direction)
Definition sdir.h:64

References _hash_dropbuf(), _hash_dropscanbuf(), _hash_getbuf(), _hash_kill_items(), _hash_readpage(), BlockNumberIsValid(), buf, fb(), HASH_READ, HashScanPosInvalidate, IndexScanDescData::indexRelation, LH_BUCKET_PAGE, LH_OVERFLOW_PAGE, IndexScanDescData::opaque, ScanDirectionIsForward, and IndexScanDescData::xs_heaptid.

Referenced by hashgetbitmap(), and hashgettuple().

◆ _hash_ovflblkno_to_bitno()

uint32 _hash_ovflblkno_to_bitno ( HashMetaPage  metap,
BlockNumber  ovflblkno 
)
extern

Definition at line 62 of file hashovfl.c.

63{
65 uint32 i;
67
68 /* Determine the split number containing this page */
69 for (i = 1; i <= splitnum; i++)
70 {
72 break; /* oops */
74
75 /*
76 * bitnum has to be greater than number of overflow page added in
77 * previous split point. The overflow page at this splitnum (i) if any
78 * should start from (_hash_get_totalbuckets(i) +
79 * metap->hashm_spares[i - 1] + 1).
80 */
81 if (bitnum > metap->hashm_spares[i - 1] &&
82 bitnum <= metap->hashm_spares[i])
83 return bitnum - 1; /* -1 to convert 1-based to 0-based */
84 }
85
88 errmsg("invalid overflow block number %u", ovflblkno)));
89 return 0; /* keep compiler quiet */
90}

References _hash_get_totalbuckets(), ereport, errcode(), errmsg, ERROR, fb(), HashMetaPageData::hashm_ovflpoint, HashMetaPageData::hashm_spares, and i.

Referenced by _hash_freeovflpage(), and hash_bitmap_info().

◆ _hash_pageinit()

void _hash_pageinit ( Page  page,
Size  size 
)
extern

Definition at line 596 of file hashpage.c.

597{
598 PageInit(page, size, sizeof(HashPageOpaqueData));
599}
void PageInit(Page page, Size pageSize, Size specialSize)
Definition bufpage.c:42

References PageInit().

Referenced by _hash_alloc_buckets(), _hash_freeovflpage(), _hash_getinitbuf(), _hash_getnewbuf(), _hash_init_metabuffer(), _hash_initbitmapbuffer(), _hash_initbuf(), and hash_xlog_squeeze_page().

◆ _hash_pgaddmultitup()

void _hash_pgaddmultitup ( Relation  rel,
Buffer  buf,
IndexTuple *  itups,
OffsetNumber *  itup_offsets,
uint16  nitups 
)
extern

Definition at line 331 of file hashinsert.c.

333{
335 Page page;
337 int i;
338
340 page = BufferGetPage(buf);
341
342 for (i = 0; i < nitups; i++)
343 {
345
346 itemsize = IndexTupleSize(itups[i]);
348
349 /* Find where to insert the tuple (preserving page's hashkey ordering) */
352
354
355 if (PageAddItem(page, itups[i], itemsize, itup_off, false, false) == InvalidOffsetNumber)
356 elog(ERROR, "failed to add index item to \"%s\"", RelationGetRelationName(rel));
357 }
358}
#define PageAddItem(page, item, size, offsetNumber, overwrite, is_heap)
Definition bufpage.h:504
OffsetNumber _hash_binsearch(Page page, uint32 hash_value)
Definition hashutil.c:350
#define InvalidOffsetNumber
Definition off.h:26

References _hash_binsearch(), _hash_checkpage(), _hash_get_indextuple_hashkey(), buf, BufferGetPage(), elog, ERROR, fb(), i, IndexTupleSize(), InvalidOffsetNumber, LH_BUCKET_PAGE, LH_OVERFLOW_PAGE, MAXALIGN, PageAddItem, and RelationGetRelationName.

Referenced by _hash_freeovflpage(), _hash_splitbucket(), and _hash_squeezebucket().

◆ _hash_pgaddtup()

OffsetNumber _hash_pgaddtup ( Relation  rel,
Buffer  buf,
Size  itemsize,
IndexTuple  itup,
bool  appendtup 
)
extern

Definition at line 276 of file hashinsert.c.

278{
280 Page page;
281
283 page = BufferGetPage(buf);
284
285 /*
286 * Find where to insert the tuple (preserving page's hashkey ordering). If
287 * 'appendtup' is true then we just insert it at the end.
288 */
289 if (appendtup)
290 {
292
293#ifdef USE_ASSERT_CHECKING
294 /* ensure this tuple's hashkey is >= the final existing tuple */
295 if (PageGetMaxOffsetNumber(page) > 0)
296 {
298 ItemId itemid;
299
300 itemid = PageGetItemId(page, PageGetMaxOffsetNumber(page));
301 lasttup = (IndexTuple) PageGetItem(page, itemid);
302
305 }
306#endif
307 }
308 else
309 {
311
313 }
314
315 if (PageAddItem(page, itup, itemsize, itup_off, false, false) == InvalidOffsetNumber)
316 elog(ERROR, "failed to add index item to \"%s\"", RelationGetRelationName(rel));
317
318 return itup_off;
319}

References _hash_binsearch(), _hash_checkpage(), _hash_get_indextuple_hashkey(), Assert, buf, BufferGetPage(), elog, ERROR, fb(), InvalidOffsetNumber, LH_BUCKET_PAGE, LH_OVERFLOW_PAGE, PageAddItem, PageGetItem(), PageGetItemId(), PageGetMaxOffsetNumber(), and RelationGetRelationName.

Referenced by _hash_doinsert().

◆ _hash_relbuf()

◆ _hash_spareindex()

uint32 _hash_spareindex ( uint32  num_bucket)
extern

Definition at line 142 of file hashutil.c.

143{
146
148
150 return splitpoint_group;
151
152 /* account for single-phase groups */
154
155 /* account for multi-phase groups before splitpoint_group */
159
160 /* account for phases within current group */
162 (((num_bucket - 1) >>
164 HASH_SPLITPOINT_PHASE_MASK); /* to 0-based value. */
165
166 return splitpoint_phases;
167}
static uint32 pg_ceil_log2_32(uint32 num)

References fb(), HASH_SPLITPOINT_GROUPS_WITH_ONE_PHASE, HASH_SPLITPOINT_PHASE_BITS, HASH_SPLITPOINT_PHASE_MASK, and pg_ceil_log2_32().

Referenced by _hash_expandtable(), and _hash_init_metabuffer().

◆ _hash_squeezebucket()

void _hash_squeezebucket ( Relation  rel,
Bucket  bucket,
BlockNumber  bucket_blkno,
Buffer  bucket_buf,
BufferAccessStrategy  bstrategy 
)
extern

Definition at line 843 of file hashovfl.c.

848{
851 Buffer wbuf;
852 Buffer rbuf;
853 Page wpage;
854 Page rpage;
857
858 /*
859 * start squeezing into the primary bucket page.
860 */
865
866 /*
867 * if there aren't any overflow pages, there's nothing to squeeze. caller
868 * is responsible for releasing the pin on primary bucket page.
869 */
870 if (!BlockNumberIsValid(wopaque->hasho_nextblkno))
871 {
873 return;
874 }
875
876 /*
877 * Find the last page in the bucket chain by starting at the base bucket
878 * page and working forward. Note: we assume that a hash bucket chain is
879 * usually smaller than the buffer ring being used by VACUUM, else using
880 * the access strategy here would be counterproductive.
881 */
884 do
885 {
886 rblkno = ropaque->hasho_nextblkno;
887 if (rbuf != InvalidBuffer)
888 _hash_relbuf(rel, rbuf);
890 rblkno,
893 bstrategy);
896 Assert(ropaque->hasho_bucket == bucket);
897 } while (BlockNumberIsValid(ropaque->hasho_nextblkno));
898
899 /*
900 * squeeze the tuples.
901 */
902 for (;;)
903 {
910 uint16 ndeletable = 0;
911 uint16 nitups = 0;
913 int i;
914 bool retain_pin = false;
915
917 /* Scan each tuple in "read" page */
922 {
923 IndexTuple itup;
924 Size itemsz;
925
926 /* skip dead tuples */
928 continue;
929
932 itemsz = IndexTupleSize(itup);
933 itemsz = MAXALIGN(itemsz);
934
935 /*
936 * Walk up the bucket chain, looking for a page big enough for
937 * this item and all other accumulated items. Exit if we reach
938 * the read page.
939 */
941 {
943 bool tups_moved = false;
944
946
947 if (wblkno == bucket_blkno)
948 retain_pin = true;
949
950 wblkno = wopaque->hasho_nextblkno;
952
953 /* don't need to move to next page if we reached the read page */
954 if (wblkno != rblkno)
956 wblkno,
959 bstrategy);
960
961 if (nitups > 0)
962 {
964
966
967 /*
968 * This operation needs to log multiple tuples, prepare
969 * WAL for that.
970 */
971 if (RelationNeedsWAL(rel))
973
975
976 /*
977 * we have to insert tuples on the "write" page, being
978 * careful to preserve hashkey ordering. (If we insert
979 * many tuples into the same "write" page it would be
980 * worth qsort'ing them).
981 */
984
985 /* Delete tuples we already moved off read page */
988
989 /* XLOG stuff */
990 if (RelationNeedsWAL(rel))
991 {
993
995 xlrec.is_prim_bucket_same_wrt = (wbuf == bucket_buf);
996
999
1000 /*
1001 * bucket buffer was not changed, but still needs to
1002 * be registered to ensure that we can acquire a
1003 * cleanup lock on it during replay.
1004 */
1005 if (!xlrec.is_prim_bucket_same_wrt)
1006 {
1008
1009 XLogRegisterBuffer(0, bucket_buf, flags);
1010 }
1011
1014 nitups * sizeof(OffsetNumber));
1015 for (i = 0; i < nitups; i++)
1016 XLogRegisterBufData(1, itups[i], tups_size[i]);
1017
1020 ndeletable * sizeof(OffsetNumber));
1021
1023 }
1024 else
1025 recptr = XLogGetFakeLSN(rel);
1026
1029
1031
1032 tups_moved = true;
1033 }
1034
1035 /*
1036 * release the lock on previous page after acquiring the lock
1037 * on next page
1038 */
1039 if (retain_pin)
1041 else
1042 _hash_relbuf(rel, wbuf);
1043
1044 /* nothing more to do if we reached the read page */
1045 if (rblkno == wblkno)
1046 {
1047 _hash_relbuf(rel, rbuf);
1048 return;
1049 }
1050
1051 wbuf = next_wbuf;
1054 Assert(wopaque->hasho_bucket == bucket);
1055 retain_pin = false;
1056
1057 /* be tidy */
1058 for (i = 0; i < nitups; i++)
1059 pfree(itups[i]);
1060 nitups = 0;
1061 all_tups_size = 0;
1062 ndeletable = 0;
1063
1064 /*
1065 * after moving the tuples, rpage would have been compacted,
1066 * so we need to rescan it.
1067 */
1068 if (tups_moved)
1069 goto readpage;
1070 }
1071
1072 /* remember tuple for deletion from "read" page */
1074
1075 /*
1076 * we need a copy of index tuples as they can be freed as part of
1077 * overflow page, however we need them to write a WAL record in
1078 * _hash_freeovflpage.
1079 */
1080 itups[nitups] = CopyIndexTuple(itup);
1081 tups_size[nitups++] = itemsz;
1082 all_tups_size += itemsz;
1083 }
1084
1085 /*
1086 * If we reach here, there are no live tuples on the "read" page ---
1087 * it was empty when we got to it, or we moved them all. So we can
1088 * just free the page without bothering with deleting tuples
1089 * individually. Then advance to the previous "read" page.
1090 *
1091 * Tricky point here: if our read and write pages are adjacent in the
1092 * bucket chain, our write lock on wbuf will conflict with
1093 * _hash_freeovflpage's attempt to update the sibling links of the
1094 * removed page. In that case, we don't need to lock it again.
1095 */
1096 rblkno = ropaque->hasho_prevblkno;
1098
1099 /* free this overflow page (releases rbuf) */
1101 tups_size, nitups, bstrategy);
1102
1103 /* be tidy */
1104 for (i = 0; i < nitups; i++)
1105 pfree(itups[i]);
1106
1107 /* are we freeing the page adjacent to wbuf? */
1108 if (rblkno == wblkno)
1109 {
1110 /* retain the pin on primary bucket page till end of bucket scan */
1111 if (wblkno == bucket_blkno)
1113 else
1114 _hash_relbuf(rel, wbuf);
1115 return;
1116 }
1117
1119 rblkno,
1120 HASH_WRITE,
1122 bstrategy);
1125 Assert(ropaque->hasho_bucket == bucket);
1126 }
1127
1128 /* NOTREACHED */
1129}
Size PageGetFreeSpaceForMultipleTuples(const PageData *page, int ntups)
Definition bufpage.c:943
void PageIndexMultiDelete(Page page, OffsetNumber *itemnos, int nitems)
Definition bufpage.c:1170
static bool PageIsEmpty(const PageData *page)
Definition bufpage.h:248
uint16_t uint16
Definition c.h:682
#define SizeOfHashMovePageContents
Definition hash_xlog.h:138
#define XLOG_HASH_MOVE_PAGE_CONTENTS
Definition hash_xlog.h:34
BlockNumber _hash_freeovflpage(Relation rel, Buffer bucketbuf, Buffer ovflbuf, Buffer wbuf, IndexTuple *itups, OffsetNumber *itup_offsets, Size *tups_size, uint16 nitups, BufferAccessStrategy bstrategy)
Definition hashovfl.c:492
IndexTuple CopyIndexTuple(IndexTuple source)
Definition indextuple.c:479
#define ItemIdIsDead(itemId)
Definition itemid.h:113
#define MaxIndexTuplesPerPage
Definition itup.h:181
#define MaxOffsetNumber
Definition off.h:28

References _hash_freeovflpage(), _hash_getbuf_with_strategy(), _hash_pgaddmultitup(), _hash_relbuf(), Assert, BlockNumberIsValid(), BUFFER_LOCK_UNLOCK, BufferGetPage(), CopyIndexTuple(), END_CRIT_SECTION, fb(), FirstOffsetNumber, HASH_WRITE, HashPageGetOpaque, i, IndexTupleSize(), InvalidBuffer, ItemIdIsDead, LH_OVERFLOW_PAGE, LockBuffer(), MarkBufferDirty(), MAXALIGN, MaxIndexTuplesPerPage, MaxOffsetNumber, xl_hash_move_page_contents::ntups, OffsetNumberNext, PageGetFreeSpaceForMultipleTuples(), PageGetItem(), PageGetItemId(), PageGetMaxOffsetNumber(), PageIndexMultiDelete(), PageIsEmpty(), PageSetLSN(), pfree(), REGBUF_NO_CHANGE, REGBUF_NO_IMAGE, REGBUF_STANDARD, RelationNeedsWAL, SizeOfHashMovePageContents, START_CRIT_SECTION, XLOG_HASH_MOVE_PAGE_CONTENTS, XLogBeginInsert(), XLogEnsureRecordSpace(), XLogGetFakeLSN(), XLogInsert(), XLogRegisterBufData(), XLogRegisterBuffer(), and XLogRegisterData().

Referenced by hashbucketcleanup().

◆ hashadjustmembers()

void hashadjustmembers ( Oid  opfamilyoid,
Oid  opclassoid,
List *  operators,
List *  functions 
)
extern

Definition at line 263 of file hashvalidate.c.

267{
268 Oid opcintype;
269 ListCell *lc;
270
271 /*
272 * Hash operators and required support functions are always "loose"
273 * members of the opfamily if they are cross-type. If they are not
274 * cross-type, we prefer to tie them to the appropriate opclass ... but if
275 * the user hasn't created one, we can't do that, and must fall back to
276 * using the opfamily dependency. (We mustn't force creation of an
277 * opclass in such a case, as leaving an incomplete opclass laying about
278 * would be bad. Throwing an error is another undesirable alternative.)
279 *
280 * This behavior results in a bit of a dump/reload hazard, in that the
281 * order of restoring objects could affect what dependencies we end up
282 * with. pg_dump's existing behavior will preserve the dependency choices
283 * in most cases, but not if a cross-type operator has been bound tightly
284 * into an opclass. That's a mistake anyway, so silently "fixing" it
285 * isn't awful.
286 *
287 * Optional support functions are always "loose" family members.
288 *
289 * To avoid repeated lookups, we remember the most recently used opclass's
290 * input type.
291 */
292 if (OidIsValid(opclassoid))
293 {
294 /* During CREATE OPERATOR CLASS, need CCI to see the pg_opclass row */
296 opcintype = get_opclass_input_type(opclassoid);
297 }
298 else
299 opcintype = InvalidOid;
300
301 /*
302 * We handle operators and support functions almost identically, so rather
303 * than duplicate this code block, just join the lists.
304 */
305 foreach(lc, list_concat_copy(operators, functions))
306 {
308
309 if (op->is_func && op->number != HASHSTANDARD_PROC)
310 {
311 /* Optional support proc, so always a soft family dependency */
312 op->ref_is_hard = false;
313 op->ref_is_family = true;
314 op->refobjid = opfamilyoid;
315 }
316 else if (op->lefttype != op->righttype)
317 {
318 /* Cross-type, so always a soft family dependency */
319 op->ref_is_hard = false;
320 op->ref_is_family = true;
321 op->refobjid = opfamilyoid;
322 }
323 else
324 {
325 /* Not cross-type; is there a suitable opclass? */
326 if (op->lefttype != opcintype)
327 {
328 /* Avoid repeating this expensive lookup, even if it fails */
329 opcintype = op->lefttype;
332 opcintype);
333 }
334 if (OidIsValid(opclassoid))
335 {
336 /* Hard dependency on opclass */
337 op->ref_is_hard = true;
338 op->ref_is_family = false;
339 op->refobjid = opclassoid;
340 }
341 else
342 {
343 /* We're stuck, so make a soft dependency on the opfamily */
344 op->ref_is_hard = false;
345 op->ref_is_family = true;
346 op->refobjid = opfamilyoid;
347 }
348 }
349 }
350}
Oid opclass_for_family_datatype(Oid amoid, Oid opfamilyoid, Oid datatypeoid)
Definition amvalidate.c:236
#define OidIsValid(objectId)
Definition c.h:917
List * list_concat_copy(const List *list1, const List *list2)
Definition list.c:598
Oid get_opclass_input_type(Oid opclass)
Definition lsyscache.c:1464
#define lfirst(lc)
Definition pg_list.h:172
static const struct fns functions
Definition regcomp.c:358
Oid refobjid
Definition amapi.h:98
Oid lefttype
Definition amapi.h:93
bool ref_is_family
Definition amapi.h:97
Oid righttype
Definition amapi.h:94
bool is_func
Definition amapi.h:90
bool ref_is_hard
Definition amapi.h:96
void CommandCounterIncrement(void)
Definition xact.c:1130

References CommandCounterIncrement(), fb(), functions, get_opclass_input_type(), HASHSTANDARD_PROC, InvalidOid, OpFamilyMember::is_func, OpFamilyMember::lefttype, lfirst, list_concat_copy(), OpFamilyMember::number, OidIsValid, opclass_for_family_datatype(), OpFamilyMember::ref_is_family, OpFamilyMember::ref_is_hard, OpFamilyMember::refobjid, and OpFamilyMember::righttype.

Referenced by hashhandler().

◆ hashbeginscan()

IndexScanDesc hashbeginscan ( Relation  rel,
int  nkeys,
int  norderbys 
)
extern

Definition at line 386 of file hash.c.

387{
388 IndexScanDesc scan;
390
391 /* no order by operators allowed */
392 Assert(norderbys == 0);
393
394 scan = RelationGetIndexScan(rel, nkeys, norderbys);
395
397 HashScanPosInvalidate(so->currPos);
398 so->hashso_bucket_buf = InvalidBuffer;
399 so->hashso_split_bucket_buf = InvalidBuffer;
400
401 so->hashso_buc_populated = false;
402 so->hashso_buc_split = false;
403
404 so->killedItems = NULL;
405 so->numKilled = 0;
406
407 scan->opaque = so;
408
409 return scan;
410}
#define palloc_object(type)
Definition fe_memutils.h:89
IndexScanDesc RelationGetIndexScan(Relation indexRelation, int nkeys, int norderbys)
Definition genam.c:80

References Assert, fb(), HashScanPosInvalidate, InvalidBuffer, IndexScanDescData::opaque, palloc_object, and RelationGetIndexScan().

Referenced by hashhandler().

◆ hashbucketcleanup()

void hashbucketcleanup ( Relation  rel,
Bucket  cur_bucket,
Buffer  bucket_buf,
BlockNumber  bucket_blkno,
BufferAccessStrategy  bstrategy,
uint32  maxbucket,
uint32  highmask,
uint32  lowmask,
double *  tuples_removed,
double *  num_index_tuples,
bool  split_cleanup,
IndexBulkDeleteCallback  callback,
void *  callback_state 
)
extern

Definition at line 767 of file hash.c.

773{
774 BlockNumber blkno;
775 Buffer buf;
777 bool bucket_dirty = false;
779
780 blkno = bucket_blkno;
781 buf = bucket_buf;
782
783 if (split_cleanup)
786
787 /* Scan each page in bucket */
788 for (;;)
789 {
790 HashPageOpaque opaque;
794 Page page;
796 int ndeletable = 0;
797 bool retain_pin = false;
798 bool clear_dead_marking = false;
799
800 vacuum_delay_point(false);
801
802 page = BufferGetPage(buf);
803 opaque = HashPageGetOpaque(page);
804
805 /* Scan each tuple in page */
808 offno <= maxoffno;
810 {
811 ItemPointer htup;
812 IndexTuple itup;
814 bool kill_tuple = false;
815
816 itup = (IndexTuple) PageGetItem(page,
817 PageGetItemId(page, offno));
818 htup = &(itup->t_tid);
819
820 /*
821 * To remove the dead tuples, we strictly want to rely on results
822 * of callback function. refer btvacuumpage for detailed reason.
823 */
824 if (callback && callback(htup, callback_state))
825 {
826 kill_tuple = true;
827 if (tuples_removed)
828 *tuples_removed += 1;
829 }
830 else if (split_cleanup)
831 {
832 /* delete the tuples that are moved by split. */
834 maxbucket,
835 highmask,
836 lowmask);
837 /* mark the item for deletion */
838 if (bucket != cur_bucket)
839 {
840 /*
841 * We expect tuples to either belong to current bucket or
842 * new_bucket. This is ensured because we don't allow
843 * further splits from bucket that contains garbage. See
844 * comments in _hash_expandtable.
845 */
846 Assert(bucket == new_bucket);
847 kill_tuple = true;
848 }
849 }
850
851 if (kill_tuple)
852 {
853 /* mark the item for deletion */
855 }
856 else
857 {
858 /* we're keeping it, so count it */
859 if (num_index_tuples)
860 *num_index_tuples += 1;
861 }
862 }
863
864 /* retain the pin on primary bucket page till end of bucket scan */
865 if (blkno == bucket_blkno)
866 retain_pin = true;
867 else
868 retain_pin = false;
869
870 blkno = opaque->hasho_nextblkno;
871
872 /*
873 * Apply deletions, advance to next page and write page if needed.
874 */
875 if (ndeletable > 0)
876 {
877 /* No ereport(ERROR) until changes are logged */
879
881 bucket_dirty = true;
882
883 /*
884 * Let us mark the page as clean if vacuum removes the DEAD tuples
885 * from an index page. We do this by clearing
886 * LH_PAGE_HAS_DEAD_TUPLES flag.
887 */
888 if (tuples_removed && *tuples_removed > 0 &&
889 H_HAS_DEAD_TUPLES(opaque))
890 {
892 clear_dead_marking = true;
893 }
894
896
897 /* XLOG stuff */
898 if (RelationNeedsWAL(rel))
899 {
901
902 xlrec.clear_dead_marking = clear_dead_marking;
903 xlrec.is_primary_bucket_page = (buf == bucket_buf);
904
907
908 /*
909 * bucket buffer was not changed, but still needs to be
910 * registered to ensure that we can acquire a cleanup lock on
911 * it during replay.
912 */
913 if (!xlrec.is_primary_bucket_page)
914 {
916
918 }
919
922 ndeletable * sizeof(OffsetNumber));
923
925 }
926 else
927 recptr = XLogGetFakeLSN(rel);
928
930
932 }
933
934 /* bail out if there are no more pages to scan. */
935 if (!BlockNumberIsValid(blkno))
936 break;
937
940 bstrategy);
941
942 /*
943 * release the lock on previous page after acquiring the lock on next
944 * page
945 */
946 if (retain_pin)
948 else
949 _hash_relbuf(rel, buf);
950
951 buf = next_buf;
952 }
953
954 /*
955 * lock the bucket page to clear the garbage flag and squeeze the bucket.
956 * if the current buffer is same as bucket buffer, then we already have
957 * lock on bucket page.
958 */
959 if (buf != bucket_buf)
960 {
961 _hash_relbuf(rel, buf);
963 }
964
965 /*
966 * Clear the garbage flag from bucket after deleting the tuples that are
967 * moved by split. We purposefully clear the flag before squeeze bucket,
968 * so that after restart, vacuum shouldn't again try to delete the moved
969 * by split tuples.
970 */
971 if (split_cleanup)
972 {
974 Page page;
975
978
979 /* No ereport(ERROR) until changes are logged */
981
984
985 /* XLOG stuff */
986 if (RelationNeedsWAL(rel))
987 {
990
992 }
993 else
994 recptr = XLogGetFakeLSN(rel);
995
996 PageSetLSN(page, recptr);
997
999 }
1000
1001 /*
1002 * If we have deleted anything, try to compact free space. For squeezing
1003 * the bucket, we must have a cleanup lock, else it can impact the
1004 * ordering of tuples for a scan that has started before it.
1005 */
1008 bstrategy);
1009 else
1011}
#define XLOG_HASH_SPLIT_CLEANUP
Definition hash_xlog.h:37
#define SizeOfHashDelete
Definition hash_xlog.h:187
#define XLOG_HASH_DELETE
Definition hash_xlog.h:36
void _hash_squeezebucket(Relation rel, Bucket bucket, BlockNumber bucket_blkno, Buffer bucket_buf, BufferAccessStrategy bstrategy)
Definition hashovfl.c:843
bool clear_dead_marking
Definition hash_xlog.h:181
static void callback(struct sockaddr *addr, struct sockaddr *mask, void *unused)
void vacuum_delay_point(bool is_analyze)
Definition vacuum.c:2438

References _hash_get_indextuple_hashkey(), _hash_get_newbucket_from_oldbucket(), _hash_getbuf_with_strategy(), _hash_hashkey2bucket(), _hash_relbuf(), _hash_squeezebucket(), Assert, BlockNumberIsValid(), buf, BUFFER_LOCK_EXCLUSIVE, BUFFER_LOCK_UNLOCK, BufferGetPage(), callback(), xl_hash_delete::clear_dead_marking, END_CRIT_SECTION, fb(), FirstOffsetNumber, H_HAS_DEAD_TUPLES, HASH_WRITE, HashPageOpaqueData::hasho_flag, HashPageOpaqueData::hasho_nextblkno, HashPageGetOpaque, InvalidBucket, IsBufferCleanupOK(), LH_OVERFLOW_PAGE, LockBuffer(), MarkBufferDirty(), MaxOffsetNumber, OffsetNumberNext, PageGetItem(), PageGetItemId(), PageGetMaxOffsetNumber(), PageIndexMultiDelete(), PageSetLSN(), PG_USED_FOR_ASSERTS_ONLY, REGBUF_NO_CHANGE, REGBUF_NO_IMAGE, REGBUF_STANDARD, RelationNeedsWAL, SizeOfHashDelete, START_CRIT_SECTION, IndexTupleData::t_tid, vacuum_delay_point(), XLOG_HASH_DELETE, XLOG_HASH_SPLIT_CLEANUP, XLogBeginInsert(), XLogGetFakeLSN(), XLogInsert(), XLogRegisterBufData(), XLogRegisterBuffer(), and XLogRegisterData().

Referenced by _hash_expandtable(), _hash_splitbucket(), and hashbulkdelete().

◆ hashbuild()

IndexBuildResult * hashbuild ( Relation  heap,
Relation  index,
struct IndexInfo *  indexInfo 
)
extern

Definition at line 135 of file hash.c.

136{
138 BlockNumber relpages;
139 double reltuples;
140 double allvisfrac;
144
145 /*
146 * We expect to be called exactly once for any index relation. If that's
147 * not the case, big trouble's what we have.
148 */
150 elog(ERROR, "index \"%s\" already contains data",
152
153 /* Estimate the number of rows currently present in the table */
154 estimate_rel_size(heap, NULL, &relpages, &reltuples, &allvisfrac);
155
156 /* Initialize the hash index metadata page and initial buckets */
158
159 /*
160 * If we just insert the tuples into the index in scan order, then
161 * (assuming their hash codes are pretty random) there will be no locality
162 * of access to the index, and if the index is bigger than available RAM
163 * then we'll thrash horribly. To prevent that scenario, we can sort the
164 * tuples by (expected) bucket number. However, such a sort is useless
165 * overhead when the index does fit in RAM. We choose to sort if the
166 * initial index size exceeds maintenance_work_mem, or the number of
167 * buffers usable for the index, whichever is less. (Limiting by the
168 * number of buffers should reduce thrashing between PG buffers and kernel
169 * buffers, which seems useful even if no physical I/O results. Limiting
170 * by maintenance_work_mem is useful to allow easy testing of the sort
171 * code path, and may be useful to DBAs as an additional control knob.)
172 *
173 * NOTE: this test will need adjustment if a bucket is ever different from
174 * one page. Also, "initial index size" accounting does not include the
175 * metapage, nor the first bitmap page.
176 */
178 if (index->rd_rel->relpersistence != RELPERSISTENCE_TEMP)
180 else
182
185 else
186 buildstate.spool = NULL;
187
188 /* prepare to build the index */
189 buildstate.indtuples = 0;
190 buildstate.heapRel = heap;
191
192 /* do the heap scan */
193 reltuples = table_index_build_scan(heap, index, indexInfo, true, true,
195 &buildstate, NULL);
197 buildstate.indtuples);
198
199 if (buildstate.spool)
200 {
201 /* sort the tuples and insert them into the index */
202 _h_indexbuild(buildstate.spool, buildstate.heapRel);
204 }
205
206 /*
207 * Return statistics
208 */
210
211 result->heap_tuples = reltuples;
212 result->index_tuples = buildstate.indtuples;
213
214 return result;
215}
#define RelationGetNumberOfBlocks(reln)
Definition bufmgr.h:309
#define Min(x, y)
Definition c.h:1131
uint32 result
int NBuffers
Definition globals.c:144
static void hashbuildCallback(Relation index, ItemPointer tid, Datum *values, bool *isnull, bool tupleIsAlive, void *state)
Definition hash.c:230
uint32 _hash_init(Relation rel, double num_tuples, ForkNumber forkNum)
Definition hashpage.c:327
void _h_indexbuild(HSpool *hspool, Relation heapRel)
Definition hashsort.c:120
HSpool * _h_spoolinit(Relation heap, Relation index, uint32 num_buckets)
Definition hashsort.c:60
void _h_spooldestroy(HSpool *hspool)
Definition hashsort.c:99
int NLocBuffer
Definition localbuf.c:45
void estimate_rel_size(Relation rel, int32 *attr_widths, BlockNumber *pages, double *tuples, double *allvisfrac)
Definition plancat.c:1305
#define PROGRESS_CREATEIDX_TUPLES_TOTAL
Definition progress.h:115
static double table_index_build_scan(Relation table_rel, Relation index_rel, IndexInfo *index_info, bool allow_sync, bool progress, IndexBuildCallback callback, void *callback_state, TableScanDesc scan)
Definition tableam.h:1845

References _h_indexbuild(), _h_spooldestroy(), _h_spoolinit(), _hash_init(), elog, ERROR, estimate_rel_size(), fb(), hashbuildCallback(), MAIN_FORKNUM, maintenance_work_mem, Min, NBuffers, NLocBuffer, palloc_object, pgstat_progress_update_param(), PROGRESS_CREATEIDX_TUPLES_TOTAL, RelationGetNumberOfBlocks, RelationGetRelationName, result, and table_index_build_scan().

Referenced by hashhandler().

◆ hashbuildempty()

void hashbuildempty ( Relation  index)
extern

Definition at line 221 of file hash.c.

222{
224}

References _hash_init(), and INIT_FORKNUM.

Referenced by hashhandler().

◆ hashbulkdelete()

IndexBulkDeleteResult * hashbulkdelete ( IndexVacuumInfo *  info,
IndexBulkDeleteResult *  stats,
IndexBulkDeleteCallback  callback,
void *  callback_state 
)
extern

Definition at line 498 of file hash.c.

500{
501 Relation rel = info->index;
502 double tuples_removed;
503 double num_index_tuples;
504 double orig_ntuples;
509 HashMetaPage metap;
512 ReadStream *stream = NULL;
514
515 tuples_removed = 0;
516 num_index_tuples = 0;
517
518 /*
519 * We need a copy of the metapage so that we can use its hashm_spares[]
520 * values to compute bucket page addresses, but a cached copy should be
521 * good enough. (If not, we'll detect that further down and refresh the
522 * cache as necessary.)
523 */
526
527 orig_maxbucket = cachedmetap->hashm_maxbucket;
528 orig_ntuples = cachedmetap->hashm_ntuples;
529
530 /* Scan the buckets that we know exist */
531 cur_bucket = 0;
533
534 /* Set up streaming read for primary bucket pages */
536 stream_private.next_bucket = cur_bucket;
537 stream_private.max_bucket = cur_maxbucket;
538
539 /*
540 * It is safe to use batchmode as hash_bulkdelete_read_stream_cb takes no
541 * locks.
542 */
545 info->strategy,
546 rel,
550 0);
551
553 while (cur_bucket <= cur_maxbucket)
554 {
556 BlockNumber blkno;
558 Buffer buf;
560 Page page;
561 bool split_cleanup = false;
562
563 /* Get address of bucket's start page */
565
566 blkno = bucket_blkno;
567
568 /*
569 * We need to acquire a cleanup lock on the primary bucket page to out
570 * wait concurrent scans before deleting the dead tuples.
571 */
576
577 page = BufferGetPage(buf);
579
580 /*
581 * If the bucket contains tuples that are moved by split, then we need
582 * to delete such tuples. We can't delete such tuples if the split
583 * operation on bucket is not finished as those are needed by scans.
584 */
587 {
588 split_cleanup = true;
589
590 /*
591 * This bucket might have been split since we last held a lock on
592 * the metapage. If so, hashm_maxbucket, hashm_highmask and
593 * hashm_lowmask might be old enough to cause us to fail to remove
594 * tuples left behind by the most recent split. To prevent that,
595 * now that the primary page of the target bucket has been locked
596 * (and thus can't be further split), check whether we need to
597 * update our cached metapage data.
598 */
599 Assert(bucket_opaque->hasho_prevblkno != InvalidBlockNumber);
600 if (bucket_opaque->hasho_prevblkno > cachedmetap->hashm_maxbucket)
601 {
604
605 /*
606 * Reset stream with updated metadata for remaining buckets.
607 * The BUCKET_TO_BLKNO mapping depends on hashm_spares[],
608 * which may have changed.
609 */
611 stream_private.next_bucket = cur_bucket + 1;
612 stream_private.max_bucket = cur_maxbucket;
613 read_stream_reset(stream);
614 }
615 }
616
617 bucket_buf = buf;
618
620 cachedmetap->hashm_maxbucket,
621 cachedmetap->hashm_highmask,
622 cachedmetap->hashm_lowmask, &tuples_removed,
623 &num_index_tuples, split_cleanup,
624 callback, callback_state);
625
627
628 /* Advance to next bucket */
629 cur_bucket++;
630 }
631
634
635 /* Write-lock metapage and check for split since we started */
638
639 if (cur_maxbucket != metap->hashm_maxbucket)
640 {
641 /* There's been a split, so process the additional bucket(s) */
645 cur_maxbucket = cachedmetap->hashm_maxbucket;
646
647 /* Reset stream to process additional buckets from split */
649 stream_private.next_bucket = cur_bucket;
650 stream_private.max_bucket = cur_maxbucket;
651 read_stream_reset(stream);
652 goto bucket_loop;
653 }
654
655 /* Stream should be exhausted since we processed all buckets */
657 read_stream_end(stream);
658
659 /* Okay, we're really done. Update tuple count in metapage. */
661
662 if (orig_maxbucket == metap->hashm_maxbucket &&
663 orig_ntuples == metap->hashm_ntuples)
664 {
665 /*
666 * No one has split or inserted anything since start of scan, so
667 * believe our count as gospel.
668 */
669 metap->hashm_ntuples = num_index_tuples;
670 }
671 else
672 {
673 /*
674 * Otherwise, our count is untrustworthy since we may have
675 * double-scanned tuples in split buckets. Proceed by dead-reckoning.
676 * (Note: we still return estimated_count = false, because using this
677 * count is better than not updating reltuples at all.)
678 */
679 if (metap->hashm_ntuples > tuples_removed)
680 metap->hashm_ntuples -= tuples_removed;
681 else
682 metap->hashm_ntuples = 0;
683 num_index_tuples = metap->hashm_ntuples;
684 }
685
687
688 /* XLOG stuff */
689 if (RelationNeedsWAL(rel))
690 {
692
693 xlrec.ntuples = metap->hashm_ntuples;
694
697
699
701 }
702 else
703 recptr = XLogGetFakeLSN(rel);
704
706
708
709 _hash_relbuf(rel, metabuf);
710
711 /* return statistics */
712 if (stats == NULL)
714 stats->estimated_count = false;
715 stats->num_index_tuples = num_index_tuples;
716 stats->tuples_removed += tuples_removed;
717 /* hashvacuumcleanup will fill in num_pages */
718
719 return stats;
720}
void LockBufferForCleanup(Buffer buffer)
Definition bufmgr.c:6693
static BlockNumber hash_bulkdelete_read_stream_cb(ReadStream *stream, void *callback_private_data, void *per_buffer_data)
Definition hash.c:473
#define XLOG_HASH_UPDATE_META_PAGE
Definition hash_xlog.h:38
#define SizeOfHashUpdateMetaPage
Definition hash_xlog.h:201
void read_stream_reset(ReadStream *stream)
Buffer read_stream_next_buffer(ReadStream *stream, void **per_buffer_data)
ReadStream * read_stream_begin_relation(int flags, BufferAccessStrategy strategy, Relation rel, ForkNumber forknum, ReadStreamBlockNumberCB callback, void *callback_private_data, size_t per_buffer_data_size)
void read_stream_end(ReadStream *stream)
#define READ_STREAM_MAINTENANCE
Definition read_stream.h:28
#define READ_STREAM_USE_BATCHING
Definition read_stream.h:64
double tuples_removed
Definition genam.h:88
double num_index_tuples
Definition genam.h:87
Relation index
Definition genam.h:54
BufferAccessStrategy strategy
Definition genam.h:61

References _hash_checkpage(), _hash_dropbuf(), _hash_getbuf(), _hash_getcachedmetap(), _hash_relbuf(), Assert, BUCKET_TO_BLKNO, buf, BUFFER_LOCK_EXCLUSIVE, BUFFER_LOCK_UNLOCK, BufferGetPage(), BufferIsInvalid, BufferIsValid(), callback(), END_CRIT_SECTION, IndexBulkDeleteResult::estimated_count, fb(), H_BUCKET_BEING_SPLIT, H_NEEDS_SPLIT_CLEANUP, hash_bulkdelete_read_stream_cb(), HASH_METAPAGE, HASH_NOLOCK, hashbucketcleanup(), HashMetaPageData::hashm_maxbucket, HashMetaPageData::hashm_ntuples, HashPageGetMeta, HashPageGetOpaque, IndexVacuumInfo::index, InvalidBlockNumber, InvalidBuffer, LH_BUCKET_PAGE, LH_META_PAGE, LockBuffer(), LockBufferForCleanup(), MAIN_FORKNUM, MarkBufferDirty(), xl_hash_update_meta_page::ntuples, IndexBulkDeleteResult::num_index_tuples, PageSetLSN(), palloc0_object, read_stream_begin_relation(), read_stream_end(), READ_STREAM_MAINTENANCE, read_stream_next_buffer(), read_stream_reset(), READ_STREAM_USE_BATCHING, REGBUF_STANDARD, RelationNeedsWAL, SizeOfHashUpdateMetaPage, START_CRIT_SECTION, IndexVacuumInfo::strategy, IndexBulkDeleteResult::tuples_removed, XLOG_HASH_UPDATE_META_PAGE, XLogBeginInsert(), XLogGetFakeLSN(), XLogInsert(), XLogRegisterBuffer(), and XLogRegisterData().

Referenced by hashhandler().

◆ hashendscan()

void hashendscan ( IndexScanDesc  scan)
extern

Definition at line 446 of file hash.c.

447{
449 Relation rel = scan->indexRelation;
450
451 if (HashScanPosIsValid(so->currPos))
452 {
453 /* Before leaving current page, deal with any killed items */
454 if (so->numKilled > 0)
455 _hash_kill_items(scan);
456 }
457
458 _hash_dropscanbuf(rel, so);
459
460 if (so->killedItems != NULL)
461 pfree(so->killedItems);
462 pfree(so);
463 scan->opaque = NULL;
464}

References _hash_dropscanbuf(), _hash_kill_items(), fb(), HashScanPosIsValid, IndexScanDescData::indexRelation, IndexScanDescData::opaque, and pfree().

Referenced by hashhandler().

◆ hashgetbitmap()

int64 hashgetbitmap ( IndexScanDesc  scan,
TIDBitmap *  tbm 
)
extern

Definition at line 354 of file hash.c.

355{
357 bool res;
358 int64 ntids = 0;
360
362
363 while (res)
364 {
365 currItem = &so->currPos.items[so->currPos.itemIndex];
366
367 /*
368 * _hash_first and _hash_next handle eliminate dead index entries
369 * whenever scan->ignore_killed_tuples is true. Therefore, there's
370 * nothing to do here except add the results to the TIDBitmap.
371 */
372 tbm_add_tuples(tbm, &(currItem->heapTid), 1, true);
373 ntids++;
374
375 res = _hash_next(scan, ForwardScanDirection);
376 }
377
378 return ntids;
379}
bool _hash_first(IndexScanDesc scan, ScanDirection dir)
Definition hashsearch.c:289
bool _hash_next(IndexScanDesc scan, ScanDirection dir)
Definition hashsearch.c:49
@ ForwardScanDirection
Definition sdir.h:28
void tbm_add_tuples(TIDBitmap *tbm, const ItemPointerData *tids, int ntids, bool recheck)
Definition tidbitmap.c:367

References _hash_first(), _hash_next(), fb(), ForwardScanDirection, IndexScanDescData::opaque, and tbm_add_tuples().

Referenced by hashhandler().

◆ hashgettuple()

bool hashgettuple ( IndexScanDesc  scan,
ScanDirection  dir 
)
extern

Definition at line 303 of file hash.c.

304{
306 bool res;
307
308 /* Hash indexes are always lossy since we store only the hash code */
309 scan->xs_recheck = true;
310
311 /*
312 * If we've already initialized this scan, we can just advance it in the
313 * appropriate direction. If we haven't done so yet, we call a routine to
314 * get the first item in the scan.
315 */
316 if (!HashScanPosIsValid(so->currPos))
317 res = _hash_first(scan, dir);
318 else
319 {
320 /*
321 * Check to see if we should kill the previously-fetched tuple.
322 */
323 if (scan->kill_prior_tuple)
324 {
325 /*
326 * Yes, so remember it for later. (We'll deal with all such tuples
327 * at once right after leaving the index page or at end of scan.)
328 * In case if caller reverses the indexscan direction it is quite
329 * possible that the same item might get entered multiple times.
330 * But, we don't detect that; instead, we just forget any excess
331 * entries.
332 */
333 if (so->killedItems == NULL)
334 so->killedItems = palloc_array(int, MaxIndexTuplesPerPage);
335
336 if (so->numKilled < MaxIndexTuplesPerPage)
337 so->killedItems[so->numKilled++] = so->currPos.itemIndex;
338 }
339
340 /*
341 * Now continue the scan.
342 */
343 res = _hash_next(scan, dir);
344 }
345
346 return res;
347}
#define palloc_array(type, count)
Definition fe_memutils.h:91
bool kill_prior_tuple
Definition relscan.h:160

References _hash_first(), _hash_next(), fb(), HashScanPosIsValid, IndexScanDescData::kill_prior_tuple, MaxIndexTuplesPerPage, IndexScanDescData::opaque, palloc_array, and IndexScanDescData::xs_recheck.

Referenced by hashhandler().

◆ hashinsert()

bool hashinsert ( Relation  rel,
Datum *  values,
bool *  isnull,
ItemPointer  ht_ctid,
Relation  heapRel,
IndexUniqueCheck  checkUnique,
bool  indexUnchanged,
struct IndexInfo *  indexInfo 
)
extern

Definition at line 271 of file hash.c.

276{
278 bool index_isnull[1];
279 IndexTuple itup;
280
281 /* convert data to a hash key; on failure, do not insert anything */
282 if (!_hash_convert_tuple(rel,
283 values, isnull,
285 return false;
286
287 /* form an index tuple and point it at the heap tuple */
289 itup->t_tid = *ht_ctid;
290
291 _hash_doinsert(rel, itup, heapRel, false);
292
293 pfree(itup);
294
295 return false;
296}
bool _hash_convert_tuple(Relation index, const Datum *user_values, const bool *user_isnull, Datum *index_values, bool *index_isnull)
Definition hashutil.c:318
IndexTuple index_form_tuple(TupleDesc tupleDescriptor, const Datum *values, const bool *isnull)
Definition indextuple.c:44

References _hash_convert_tuple(), _hash_doinsert(), fb(), index_form_tuple(), pfree(), RelationGetDescr, IndexTupleData::t_tid, and values.

Referenced by hashhandler().

◆ hashoptions()

bytea * hashoptions ( Datum  reloptions,
bool  validate 
)
extern

Definition at line 275 of file hashutil.c.

276{
277 static const relopt_parse_elt tab[] = {
279 };
280
281 return (bytea *) build_reloptions(reloptions, validate,
283 sizeof(HashOptions),
284 tab, lengthof(tab));
285}
static bool validate(Port *port, const char *auth, const char **logdetail)
Definition auth-oauth.c:672
#define lengthof(array)
Definition c.h:932
static int fillfactor
Definition pgbench.c:188
void * build_reloptions(Datum reloptions, bool validate, relopt_kind kind, Size relopt_struct_size, const relopt_parse_elt *relopt_elems, int num_relopt_elems)
@ RELOPT_KIND_HASH
Definition reloptions.h:45
@ RELOPT_TYPE_INT
Definition reloptions.h:32
Definition c.h:835

References build_reloptions(), fb(), fillfactor, lengthof, RELOPT_KIND_HASH, RELOPT_TYPE_INT, and validate().

Referenced by hashhandler().

◆ hashrescan()

void hashrescan ( IndexScanDesc  scan,
ScanKey  scankey,
int  nscankeys,
ScanKey  orderbys,
int  norderbys 
)
extern

Definition at line 416 of file hash.c.

418{
420 Relation rel = scan->indexRelation;
421
422 if (HashScanPosIsValid(so->currPos))
423 {
424 /* Before leaving current page, deal with any killed items */
425 if (so->numKilled > 0)
426 _hash_kill_items(scan);
427 }
428
429 _hash_dropscanbuf(rel, so);
430
431 /* set position invalid (this will cause _hash_first call) */
432 HashScanPosInvalidate(so->currPos);
433
434 /* Update scan key, if a new one is given */
435 if (scankey && scan->numberOfKeys > 0)
436 memcpy(scan->keyData, scankey, scan->numberOfKeys * sizeof(ScanKeyData));
437
438 so->hashso_buc_populated = false;
439 so->hashso_buc_split = false;
440}

References _hash_dropscanbuf(), _hash_kill_items(), fb(), HashScanPosInvalidate, HashScanPosIsValid, IndexScanDescData::indexRelation, IndexScanDescData::keyData, memcpy(), IndexScanDescData::numberOfKeys, and IndexScanDescData::opaque.

Referenced by hashhandler().

◆ hashtranslatecmptype()

StrategyNumber hashtranslatecmptype ( CompareType  cmptype,
Oid  opfamily 
)
extern

Definition at line 1022 of file hash.c.

1023{
1024 if (cmptype == COMPARE_EQ)
1025 return HTEqualStrategyNumber;
1026 return InvalidStrategy;
1027}
@ COMPARE_EQ
Definition cmptype.h:36
#define InvalidStrategy
Definition stratnum.h:24

References COMPARE_EQ, HTEqualStrategyNumber, and InvalidStrategy.

Referenced by hashhandler().

◆ hashtranslatestrategy()

CompareType hashtranslatestrategy ( StrategyNumber  strategy,
Oid  opfamily 
)
extern

Definition at line 1014 of file hash.c.

1015{
1016 if (strategy == HTEqualStrategyNumber)
1017 return COMPARE_EQ;
1018 return COMPARE_INVALID;
1019}
@ COMPARE_INVALID
Definition cmptype.h:33

References COMPARE_EQ, COMPARE_INVALID, and HTEqualStrategyNumber.

Referenced by hashhandler().

◆ hashvacuumcleanup()

IndexBulkDeleteResult * hashvacuumcleanup ( IndexVacuumInfo *  info,
IndexBulkDeleteResult *  stats 
)
extern

Definition at line 728 of file hash.c.

729{
730 Relation rel = info->index;
731 BlockNumber num_pages;
732
733 /* If hashbulkdelete wasn't called, return NULL signifying no change */
734 /* Note: this covers the analyze_only case too */
735 if (stats == NULL)
736 return NULL;
737
738 /* update statistics */
739 num_pages = RelationGetNumberOfBlocks(rel);
740 stats->num_pages = num_pages;
741
742 return stats;
743}
BlockNumber num_pages
Definition genam.h:85

References fb(), IndexVacuumInfo::index, IndexBulkDeleteResult::num_pages, and RelationGetNumberOfBlocks.

Referenced by hashhandler().

◆ hashvalidate()

bool hashvalidate ( Oid  opclassoid)
extern

Definition at line 40 of file hashvalidate.c.

41{
42 bool result = true;
46 Oid opcintype;
47 char *opclassname;
48 char *opfamilyname;
50 *oprlist;
54 int i;
55 ListCell *lc;
56
57 /* Fetch opclass information */
60 elog(ERROR, "cache lookup failed for operator class %u", opclassoid);
62
63 opfamilyoid = classform->opcfamily;
64 opcintype = classform->opcintype;
65 opclassname = NameStr(classform->opcname);
66
67 /* Fetch opfamily information */
68 opfamilyname = get_opfamily_name(opfamilyoid, false);
69
70 /* Fetch all operators and support functions of the opfamily */
73
74 /* Check individual support functions */
75 for (i = 0; i < proclist->n_members; i++)
76 {
77 HeapTuple proctup = &proclist->members[i]->tuple;
79 bool ok;
80
81 /*
82 * All hash functions should be registered with matching left/right
83 * types
84 */
85 if (procform->amproclefttype != procform->amprocrighttype)
86 {
89 errmsg("operator family \"%s\" of access method %s contains support function %s with different left and right input types",
90 opfamilyname, "hash",
91 format_procedure(procform->amproc))));
92 result = false;
93 }
94
95 /* Check procedure numbers and function signatures */
96 switch (procform->amprocnum)
97 {
100 1, 1, procform->amproclefttype);
101 break;
103 ok = check_amproc_signature(procform->amproc, INT8OID, true,
104 2, 2, procform->amproclefttype, INT8OID);
105 break;
106 case HASHOPTIONS_PROC:
108 break;
109 default:
112 errmsg("operator family \"%s\" of access method %s contains function %s with invalid support number %d",
113 opfamilyname, "hash",
114 format_procedure(procform->amproc),
115 procform->amprocnum)));
116 result = false;
117 continue; /* don't want additional message */
118 }
119
120 if (!ok)
121 {
124 errmsg("operator family \"%s\" of access method %s contains function %s with wrong signature for support number %d",
125 opfamilyname, "hash",
126 format_procedure(procform->amproc),
127 procform->amprocnum)));
128 result = false;
129 }
130
131 /* Remember which types we can hash */
132 if (ok && (procform->amprocnum == HASHSTANDARD_PROC || procform->amprocnum == HASHEXTENDED_PROC))
133 {
135 }
136 }
137
138 /* Check individual operators */
139 for (i = 0; i < oprlist->n_members; i++)
140 {
141 HeapTuple oprtup = &oprlist->members[i]->tuple;
143
144 /* Check that only allowed strategy numbers exist */
145 if (oprform->amopstrategy < 1 ||
146 oprform->amopstrategy > HTMaxStrategyNumber)
147 {
150 errmsg("operator family \"%s\" of access method %s contains operator %s with invalid strategy number %d",
151 opfamilyname, "hash",
152 format_operator(oprform->amopopr),
153 oprform->amopstrategy)));
154 result = false;
155 }
156
157 /* hash doesn't support ORDER BY operators */
158 if (oprform->amoppurpose != AMOP_SEARCH ||
159 OidIsValid(oprform->amopsortfamily))
160 {
163 errmsg("operator family \"%s\" of access method %s contains invalid ORDER BY specification for operator %s",
164 opfamilyname, "hash",
165 format_operator(oprform->amopopr))));
166 result = false;
167 }
168
169 /* Check operator signature --- same for all hash strategies */
170 if (!check_amop_signature(oprform->amopopr, BOOLOID,
171 oprform->amoplefttype,
172 oprform->amoprighttype))
173 {
176 errmsg("operator family \"%s\" of access method %s contains operator %s with wrong signature",
177 opfamilyname, "hash",
178 format_operator(oprform->amopopr))));
179 result = false;
180 }
181
182 /* There should be relevant hash functions for each datatype */
183 if (!list_member_oid(hashabletypes, oprform->amoplefttype) ||
184 !list_member_oid(hashabletypes, oprform->amoprighttype))
185 {
188 errmsg("operator family \"%s\" of access method %s lacks support function for operator %s",
189 opfamilyname, "hash",
190 format_operator(oprform->amopopr))));
191 result = false;
192 }
193 }
194
195 /* Now check for inconsistent groups of operators/functions */
198 foreach(lc, grouplist)
199 {
201
202 /* Remember the group exactly matching the test opclass */
203 if (thisgroup->lefttype == opcintype &&
204 thisgroup->righttype == opcintype)
206
207 /*
208 * Complain if there seems to be an incomplete set of operators for
209 * this datatype pair (implying that we have a hash function but no
210 * operator).
211 */
212 if (thisgroup->operatorset != (1 << HTEqualStrategyNumber))
213 {
216 errmsg("operator family \"%s\" of access method %s is missing operator(s) for types %s and %s",
217 opfamilyname, "hash",
218 format_type_be(thisgroup->lefttype),
219 format_type_be(thisgroup->righttype))));
220 result = false;
221 }
222 }
223
224 /* Check that the originally-named opclass is supported */
225 /* (if group is there, we already checked it adequately above) */
226 if (!opclassgroup)
227 {
230 errmsg("operator class \"%s\" of access method %s is missing operator(s)",
231 opclassname, "hash")));
232 result = false;
233 }
234
235 /*
236 * Complain if the opfamily doesn't have entries for all possible
237 * combinations of its supported datatypes. While missing cross-type
238 * operators are not fatal, it seems reasonable to insist that all
239 * built-in hash opfamilies be complete.
240 */
241 if (list_length(grouplist) !=
243 {
246 errmsg("operator family \"%s\" of access method %s is missing cross-type operator(s)",
247 opfamilyname, "hash")));
248 result = false;
249 }
250
254
255 return result;
256}
bool check_amproc_signature(Oid funcid, Oid restype, bool exact, int minargs, int maxargs,...)
Definition amvalidate.c:152
bool check_amop_signature(Oid opno, Oid restype, Oid lefttype, Oid righttype)
Definition amvalidate.c:206
List * identify_opfamily_groups(CatCList *oprlist, CatCList *proclist)
Definition amvalidate.c:43
bool check_amoptsproc_signature(Oid funcid)
Definition amvalidate.c:192
#define NameStr(name)
Definition c.h:894
void ReleaseCatCacheList(CatCList *list)
Definition catcache.c:2127
#define INFO
Definition elog.h:35
char * format_type_be(Oid type_oid)
#define HASHEXTENDED_PROC
Definition hash.h:356
#define HASHOPTIONS_PROC
Definition hash.h:357
#define HeapTupleIsValid(tuple)
Definition htup.h:78
static void * GETSTRUCT(const HeapTupleData *tuple)
List * list_append_unique_oid(List *list, Oid datum)
Definition list.c:1380
bool list_member_oid(const List *list, Oid datum)
Definition list.c:722
char * get_opfamily_name(Oid opfid, bool missing_ok)
Definition lsyscache.c:1553
END_CATALOG_STRUCT typedef FormData_pg_amop * Form_pg_amop
Definition pg_amop.h:92
END_CATALOG_STRUCT typedef FormData_pg_amproc * Form_pg_amproc
Definition pg_amproc.h:72
static int list_length(const List *l)
Definition pg_list.h:152
#define NIL
Definition pg_list.h:68
END_CATALOG_STRUCT typedef FormData_pg_opclass * Form_pg_opclass
Definition pg_opclass.h:87
static Datum ObjectIdGetDatum(Oid X)
Definition postgres.h:252
char * format_procedure(Oid procedure_oid)
Definition regproc.c:305
char * format_operator(Oid operator_oid)
Definition regproc.c:801
#define HTMaxStrategyNumber
Definition stratnum.h:43
Definition pg_list.h:54
void ReleaseSysCache(HeapTuple tuple)
Definition syscache.c:265
HeapTuple SearchSysCache1(SysCacheIdentifier cacheId, Datum key1)
Definition syscache.c:221
#define SearchSysCacheList1(cacheId, key1)
Definition syscache.h:127

References check_amop_signature(), check_amoptsproc_signature(), check_amproc_signature(), elog, ereport, errcode(), errmsg, ERROR, fb(), Form_pg_amop, Form_pg_amproc, Form_pg_opclass, format_operator(), format_procedure(), format_type_be(), get_opfamily_name(), GETSTRUCT(), HASHEXTENDED_PROC, HASHOPTIONS_PROC, HASHSTANDARD_PROC, HeapTupleIsValid, HTEqualStrategyNumber, HTMaxStrategyNumber, i, identify_opfamily_groups(), INFO, lfirst, list_append_unique_oid(), list_length(), list_member_oid(), NameStr, NIL, ObjectIdGetDatum(), OidIsValid, ReleaseCatCacheList(), ReleaseSysCache(), result, SearchSysCache1(), and SearchSysCacheList1.

Referenced by hashhandler().